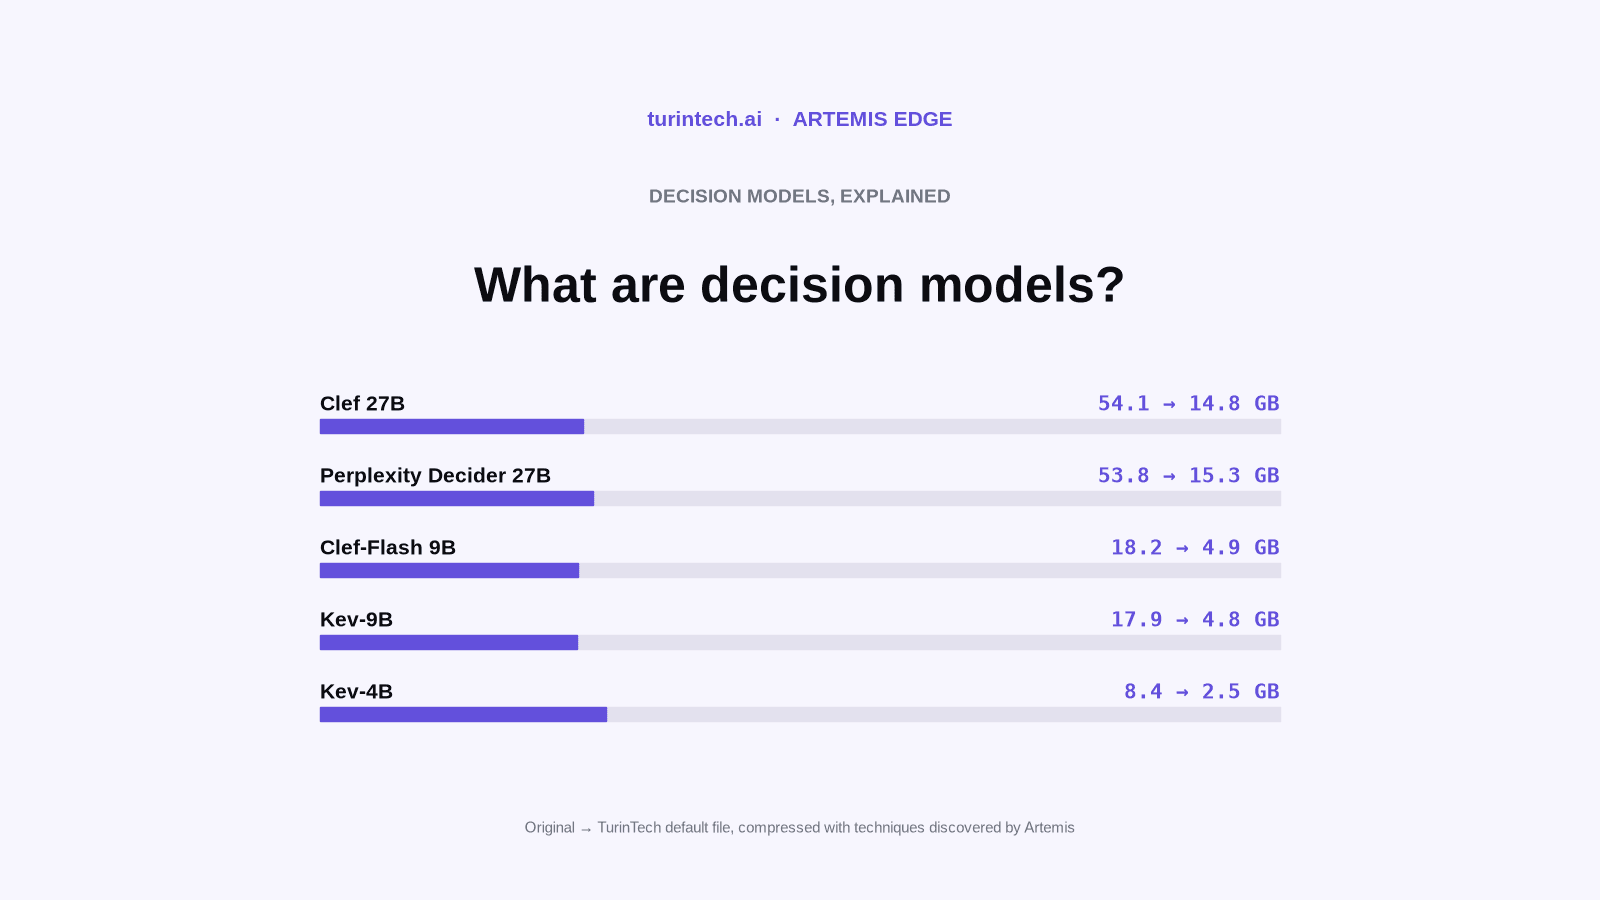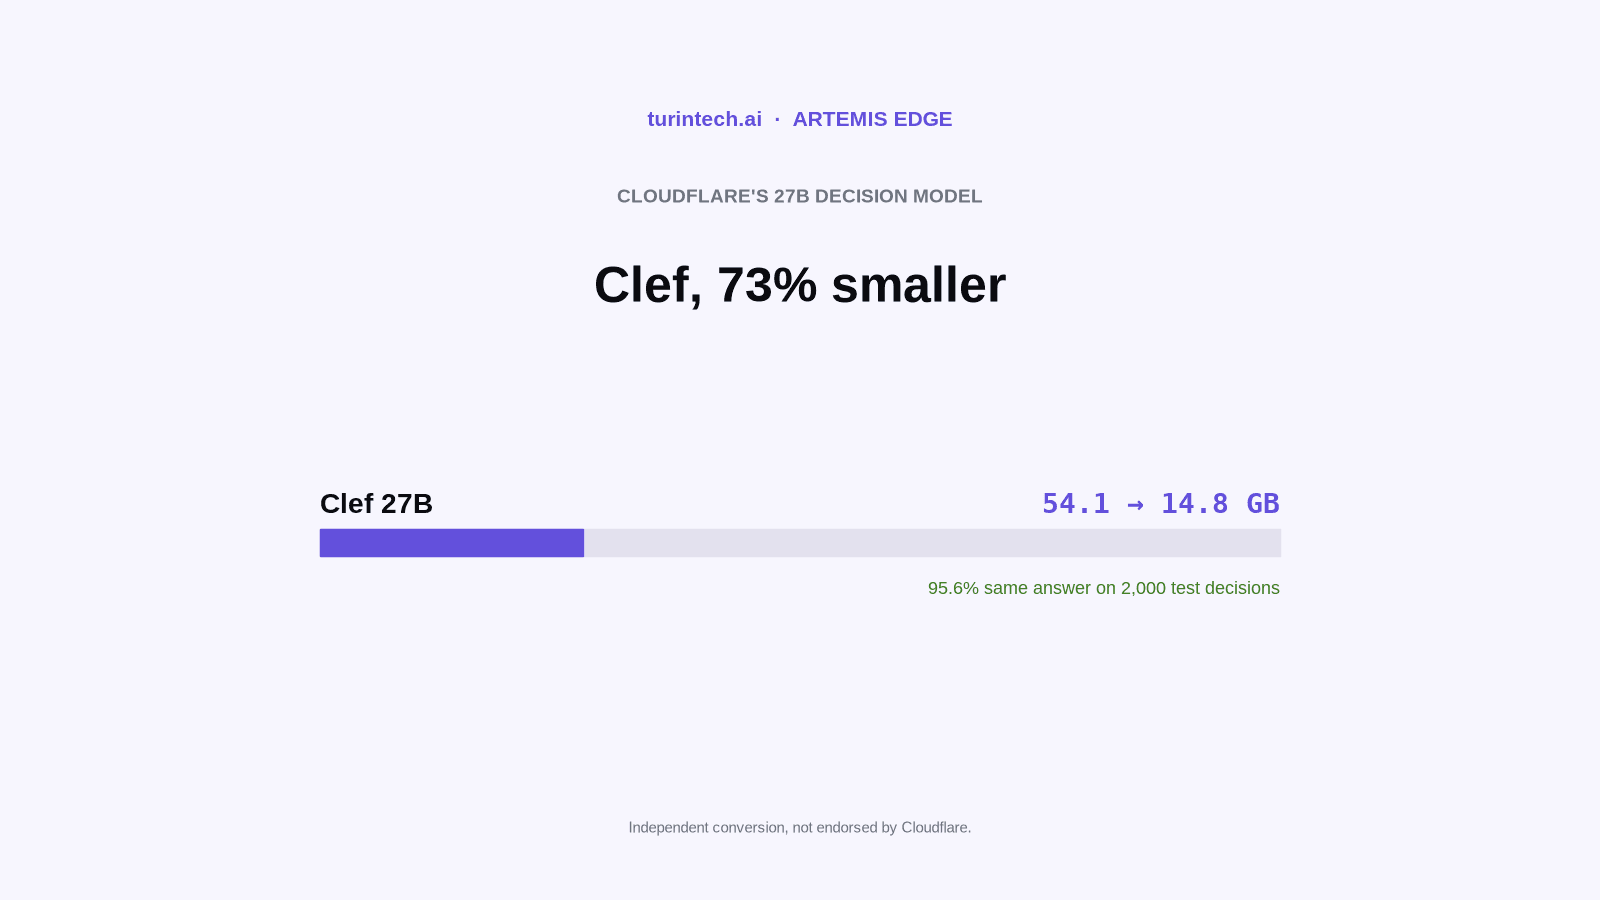
Clef is the larger of the two decision models Cloudflare released on 1 October 2026. We compressed it from 54.1 GB to 14.8 GB with techniques discovered by Artemis and checked the result against the original on thousands of decisions. If decision models are new to you, start here.
The original
Cloudflare announced Clef and its smaller sibling Clef-Flash in a post titled Introducing Clef: our open-source decision models, written by Michelle Chen, Alex Reneau and Kevin Flansburg. The models are hosted on Workers AI and published on Hugging Face under Apache 2.0, and Cloudflare says they are fully compatible with the request format TypeSafe introduced with Jev.
Clef is post-trained from Qwen3.8-27B. The Qwen backbone reads the input once, and a small head on top scores every allowed answer of every question together. Cloudflare's post points to two differences from Jev: a vision encoder, so Clef can classify images as well as text, and a 64k-token context window. At the time of release Cloudflare reported Clef leading the Decision Index benchmark suite.
The name comes from music, where a clef at the start of a staff fixes what each line means; Cloudflare also liked the "CF" in it. Its first internal use was classifying websites for Cloudflare's threat intelligence team, where Clef returns a probability for each category a domain might fall into.
What we made
The Clef Artemis GGUF repository has five files from 10.5 GB to 14.8 GB. The default, Clef-Artemis-14.8GB.gguf, is 14.82 GB, 73% smaller than the original's 54.1 GB.
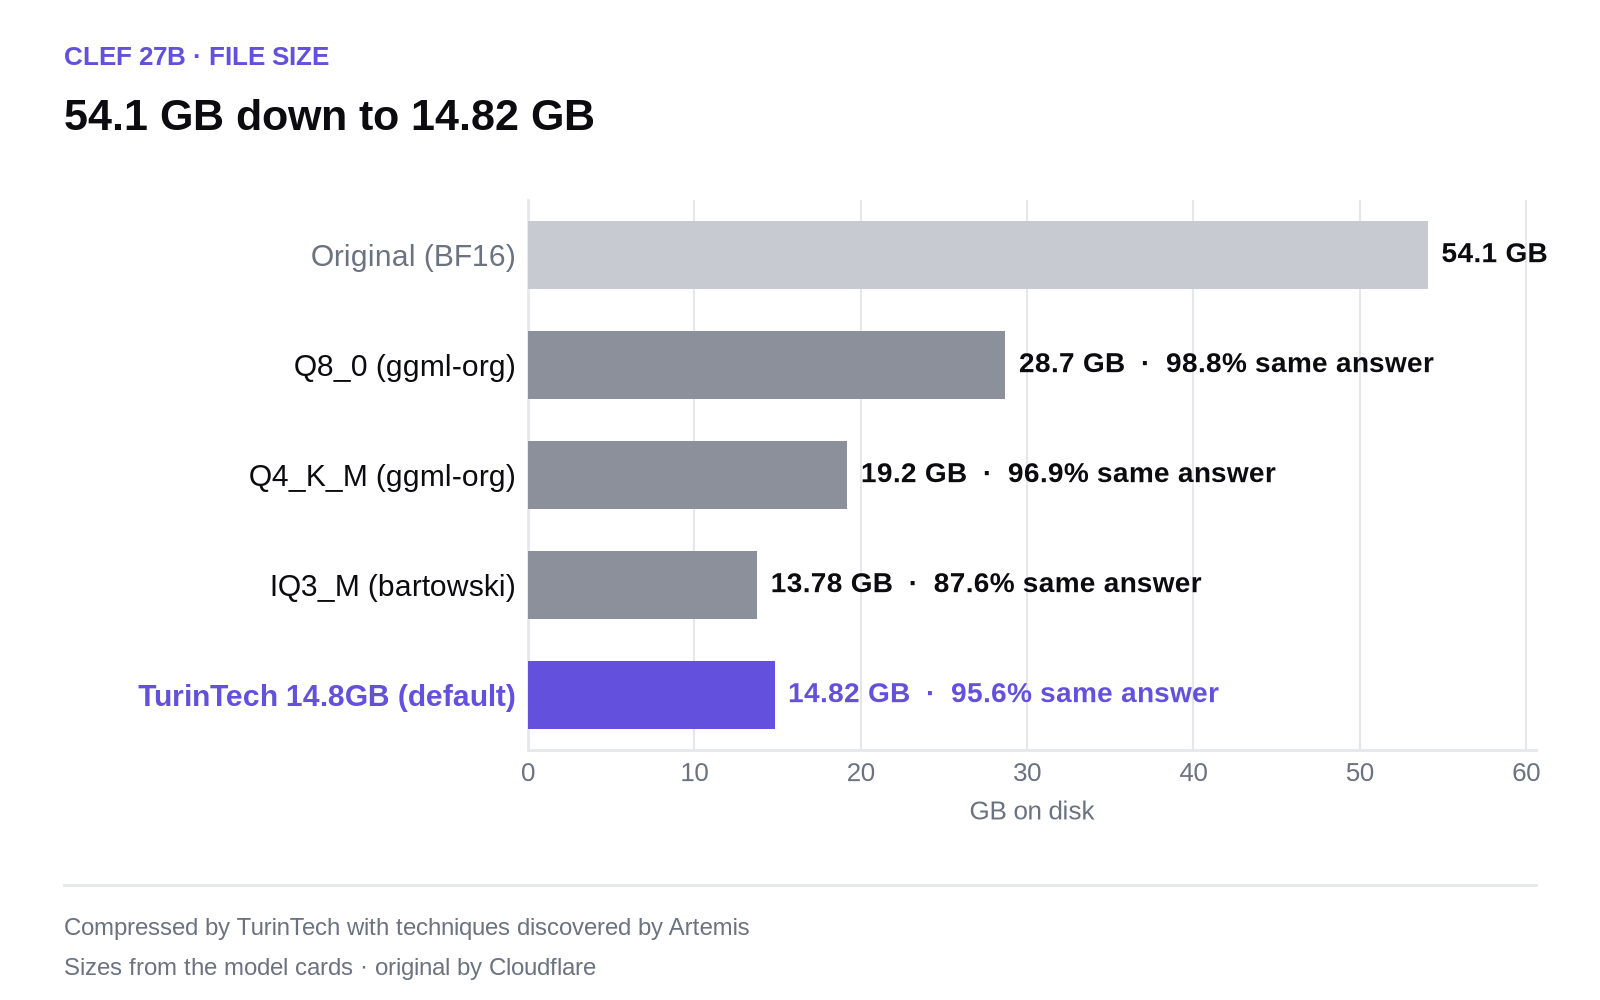
On the 2,000 test decisions, run on an NVIDIA A100, the default file gives the original's answer 95.6% of the time. Its accuracy against the dataset's labels is 72.0%, and the original's is 72.1%. It changed none of the answers the original was more than 80% sure of. On 330 image questions it gives the original's answer 94.5% of the time. On the same A100 it needs 15.0 GiB of GPU memory for text, against 49.9 GiB for the original, so it should fit a single 16 GB GPU.
| File | Size | Same answer as the original | Accuracy change (points) | Confident answers changed |
|---|---|---|---|---|
| Original, BF16 | 54.1 GB | reference | reference | |
Clef-Artemis-14.8GB (default) | 14.82 GB | 95.6% | -0.1 | 0 |
Clef-Artemis-14.3GB | 14.31 GB | 95.9% | +0.7 | 0 |
Clef-Artemis-12.7GB | 12.72 GB | 93.4% | +0.3 | 0 |
Clef-Artemis-11.5GB | 11.53 GB | 91.0% | +1.1 | 2 |
Clef-Artemis-10.5GB | 10.49 GB | 89.5% | +0.9 | 4 (+1 image) |
Accuracy changes within about one point are inside test noise.
How it compares with public files
The usual public GGUF files of Clef, run through the same tests, sit higher on agreement and are larger. The ggml-org Q8_0 (28.7 GB) gives the original's answer 98.8% of the time and the ggml-org Q4_K_M (19.2 GB) 96.9%. The closest public file in size is bartowski's IQ3_M at 13.78 GB, which agrees 87.6% of the time; our 12.7 GB file, a gigabyte smaller, agrees 93.4%.
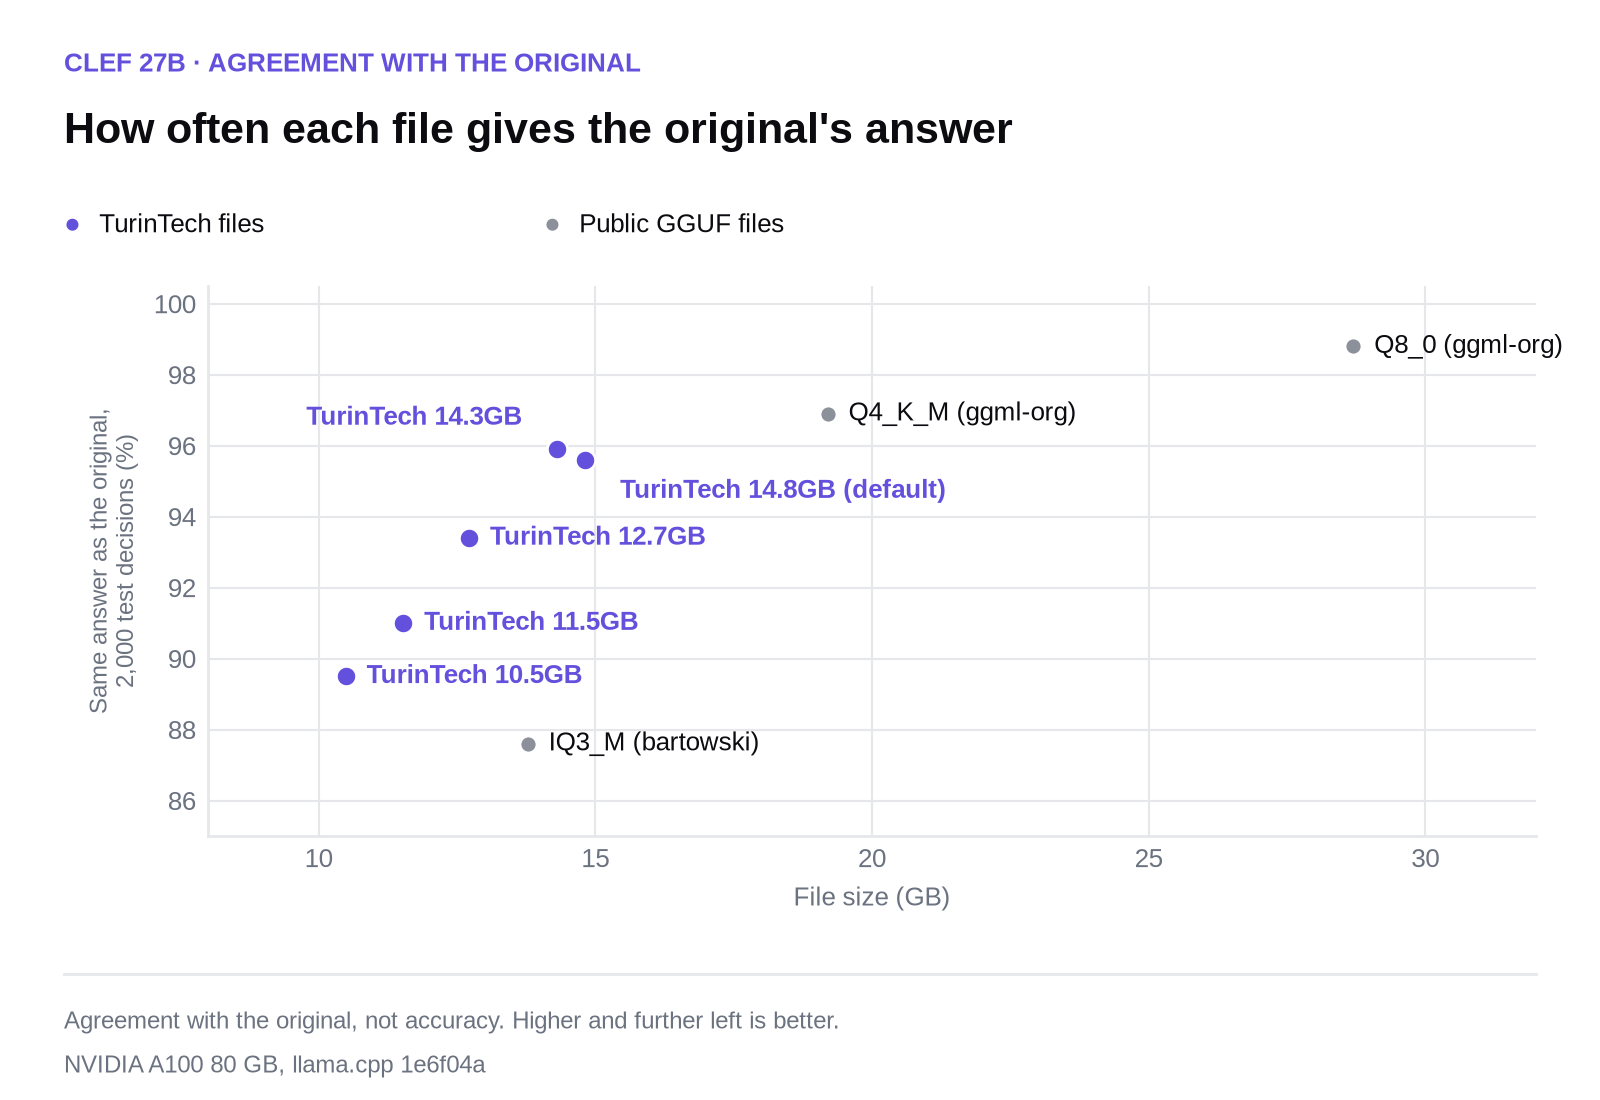
None of the public files changed a confident answer. Of ours, the two smallest did: 2 and 4 out of about 2,000. The default and the 14.3 GB file changed none.
How it was tested
Every file, ours and public, was compared with the BF16 original at identical llama.cpp settings on one NVIDIA A100 80 GB (llama.cpp commit 1e6f04a):
- 2,000 decisions from the test split of typed-decisions, 400 cases with about five questions each,
- 1,000 decisions from the dataset's train split that played no part in making the files (the default agrees on 95.4%),
- a 300-item sample of the Decision Index benchmarks (97.0%),
- 330 image questions from CV-Bench, RealWorldQA and BLINK, with the same vision projector for every file (94.5%).
Shuffling the answer options changed no answers for any file, and a repeat run gave identical answers. Clef answers all the questions in a request together, so sending the same questions one per request changes 12.8% of the original's own answers. Every number above uses the same request shape, and any comparison of files should too.
Run it
The files run on stock llama.cpp from 9 October 2026 or newer.
hf download turintech/Clef-Artemis-GGUF Clef-Artemis-14.8GB.gguf --local-dir .
llama-server -m Clef-Artemis-14.8GB.gguf --port 8080 -c 16384 -ub 4096 -b 4096
Keep -ub 4096 -b 4096: at the default of 512, /v1/systemone rejects inputs longer than 512 tokens, for every Clef GGUF. For images, add the vision projector from ggml-org/Clef-GGUF; the model card has the commands, the full test table and checksums.
This is an independent conversion, not affiliated with or endorsed by Cloudflare, and the credit for Clef belongs to Cloudflare. The files were compressed by TurinTech with techniques discovered by Artemis. Clef-Flash, the 9B model, has its own article, and the Artemis Edge collection has the rest. For a version tuned on your own decisions or built for your hardware, book a call.