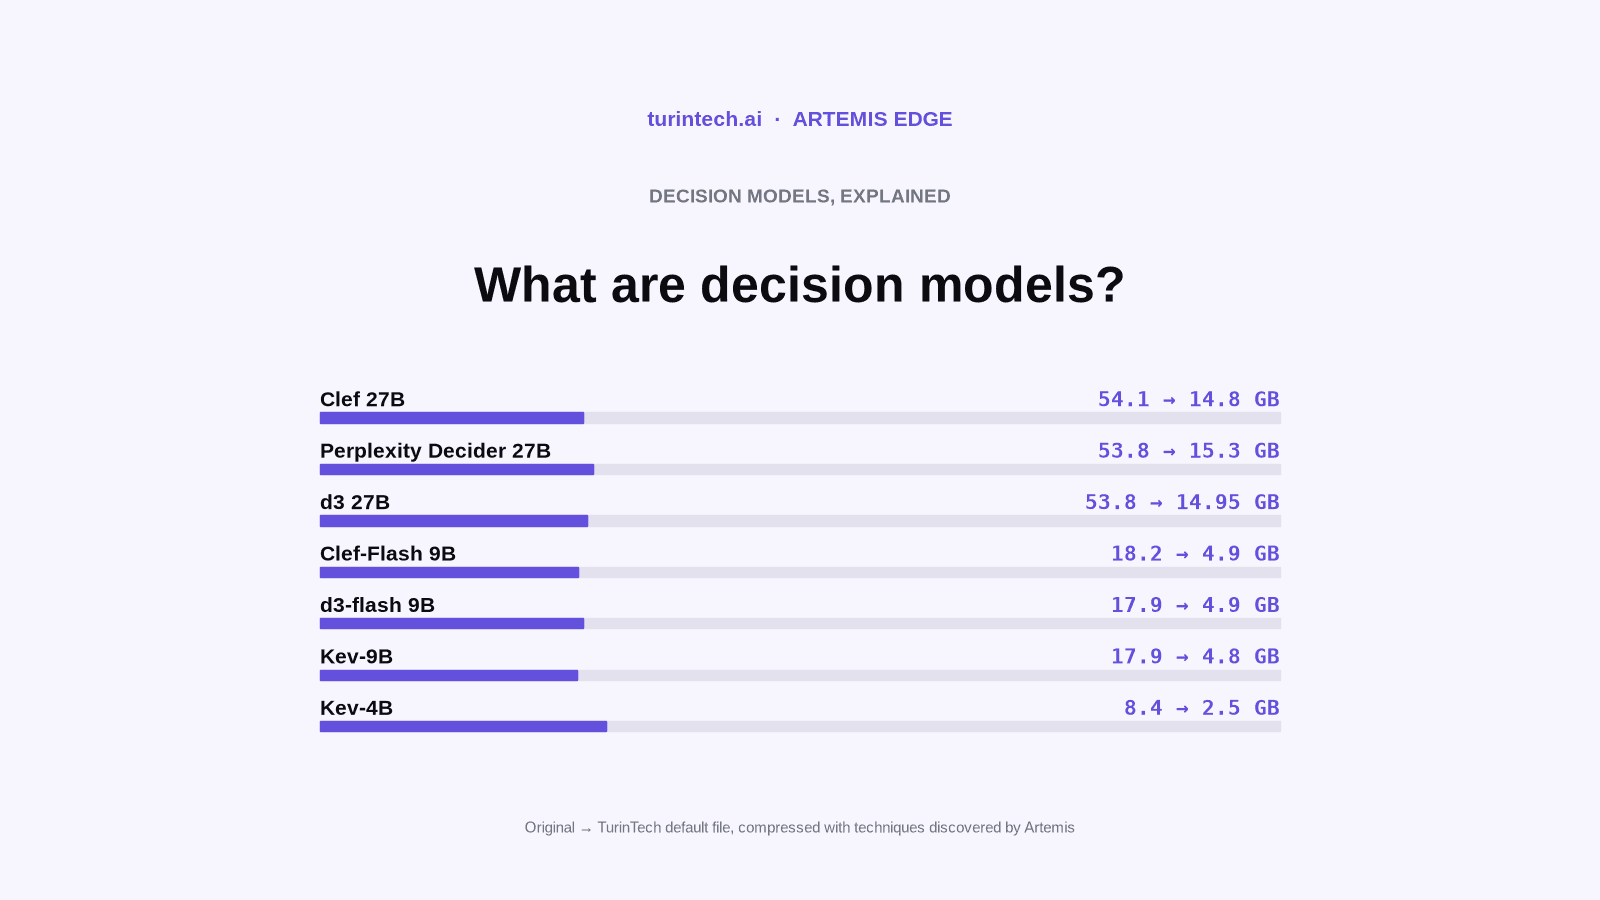
d3 and d3-flash are the two largest of the six models in Decision 3.0, the decision-model family from the open-source vLLM Semantic Router project. We compressed both with techniques discovered by Artemis and tested every file against the original. ggml-org published its own GGUF files of both models on the day llama.cpp added support for them, so this time there is a public 4-bit file to compare with. For readers new to decision models, the explainer is the place to start.
The original
vLLM Semantic Router describes itself as "an open, programmable decision layer for models and compute": it decides which model should handle each request. Decision 3.0 is its family of decision models, published on Hugging Face under Apache 2.0. d3 is the 27B model, built on Qwen3.8-27B, and d3-flash the 9B, built on Qwen3.5-9B. Both read text or JSON, images and videos, and answer pick-one, yes or no and score questions with a probability for every allowed answer. They use the same /v1/systemone request format as the other models in this series.
On the Jev Decision Index, the community benchmark for these models, vLLM Semantic Router reports d3 at 66.3 on the 0.3.2 text board, first of 149 entries when the board was read on 12 October 2026, and 10.4 points above its own Decision 2.0 27B model. It reports d3-flash at 55.8, first among the entries of a similar size (d3 card, d3-flash card). These are the authors' figures; we have not run the full index.
llama.cpp added support for d3 in release b11572 on 12 October 2026, and ggml-org published GGUF files of both models the same day.
What we made
| Model | Original | Our default file | Smaller by | Same answer as the original | Confident answers changed | Measured on |
|---|---|---|---|---|---|---|
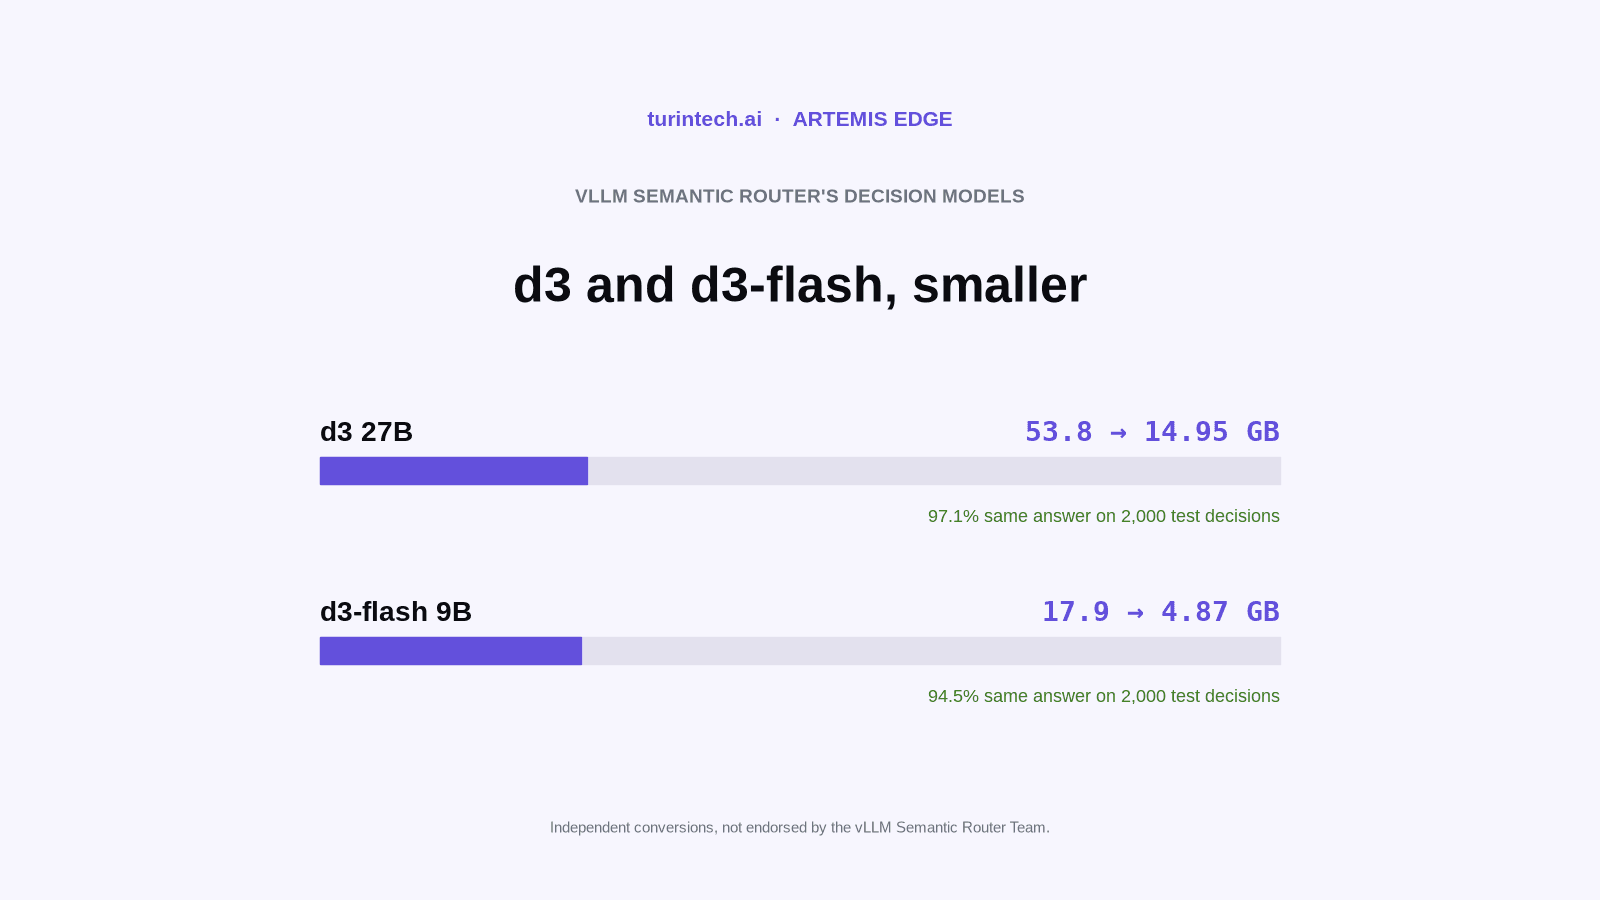
| d3 27B | 53.8 GB | 14.95 GB | 72% | 97.1% | 0 | NVIDIA RTX 5090 |
| d3-flash 9B | 17.9 GB | 4.87 GB | 73% | 94.5% | 0 | NVIDIA RTX 5090 |
Agreement is the share of 2,000 test decisions on which the file gives the original's answer. It is not accuracy. "Confident answers changed" counts answers the original was more than 80% sure of that the file changed.
d3 27B
The d3-27B Artemis GGUF default, d3-27B-Artemis-14.9GB.gguf, is 14.95 GB, 72% smaller than the original. It gives the original's answer on 97.1% of the test decisions, with accuracy 74.85% against the original's 74.60%. It changed none of the 1,109 answers the original was more than 80% sure of, in text or in images. On 330 image questions it agrees 98.5% of the time.
On an NVIDIA RTX 5090 it needs 16.4 GiB of GPU memory for text, so it should fit a 24 GB GPU. The original needs 54.6 GiB and was split over two RTX 5090s for the tests.
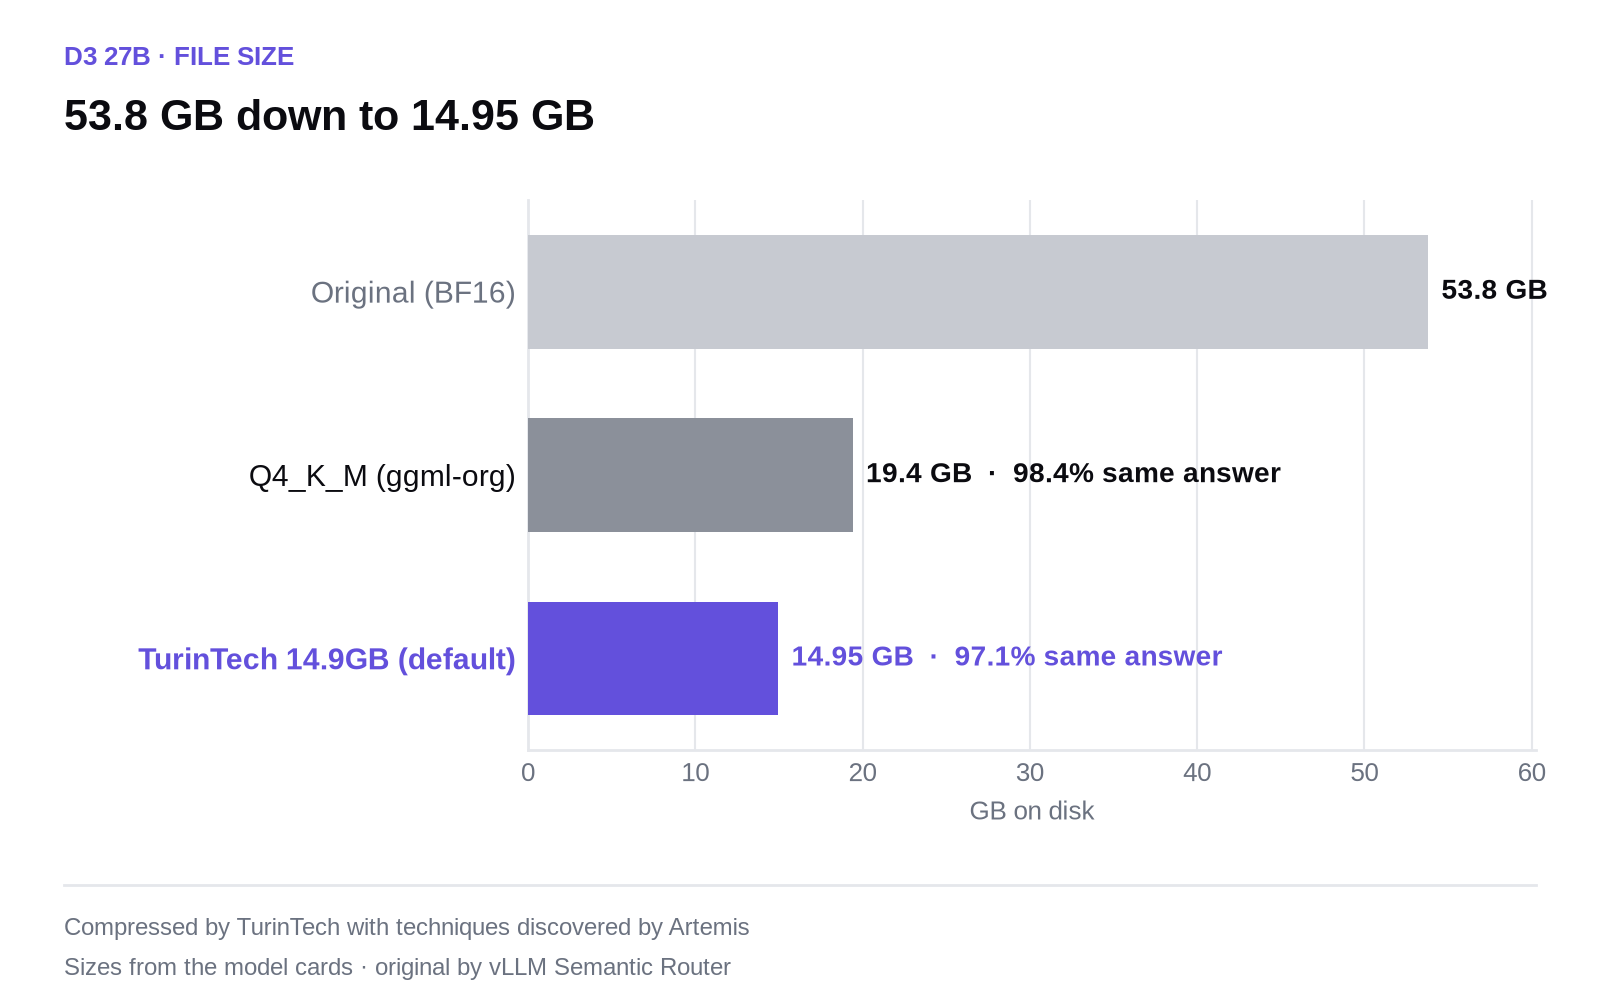
The ggml-org Q4_K_M is 19.40 GB and closer to the original on text: 98.4% on the test decisions against our 97.1%, and 97.9% on the held-out ones against our 96.8%. Our default is 23% smaller and closer on images (98.5% against 97.6%). The card also reports a weakness of our files that the test decisions do not show: on the held-out decisions they are 1.6 and 1.7 points less accurate than the original, against 0.4 points for the Q4_K_M.
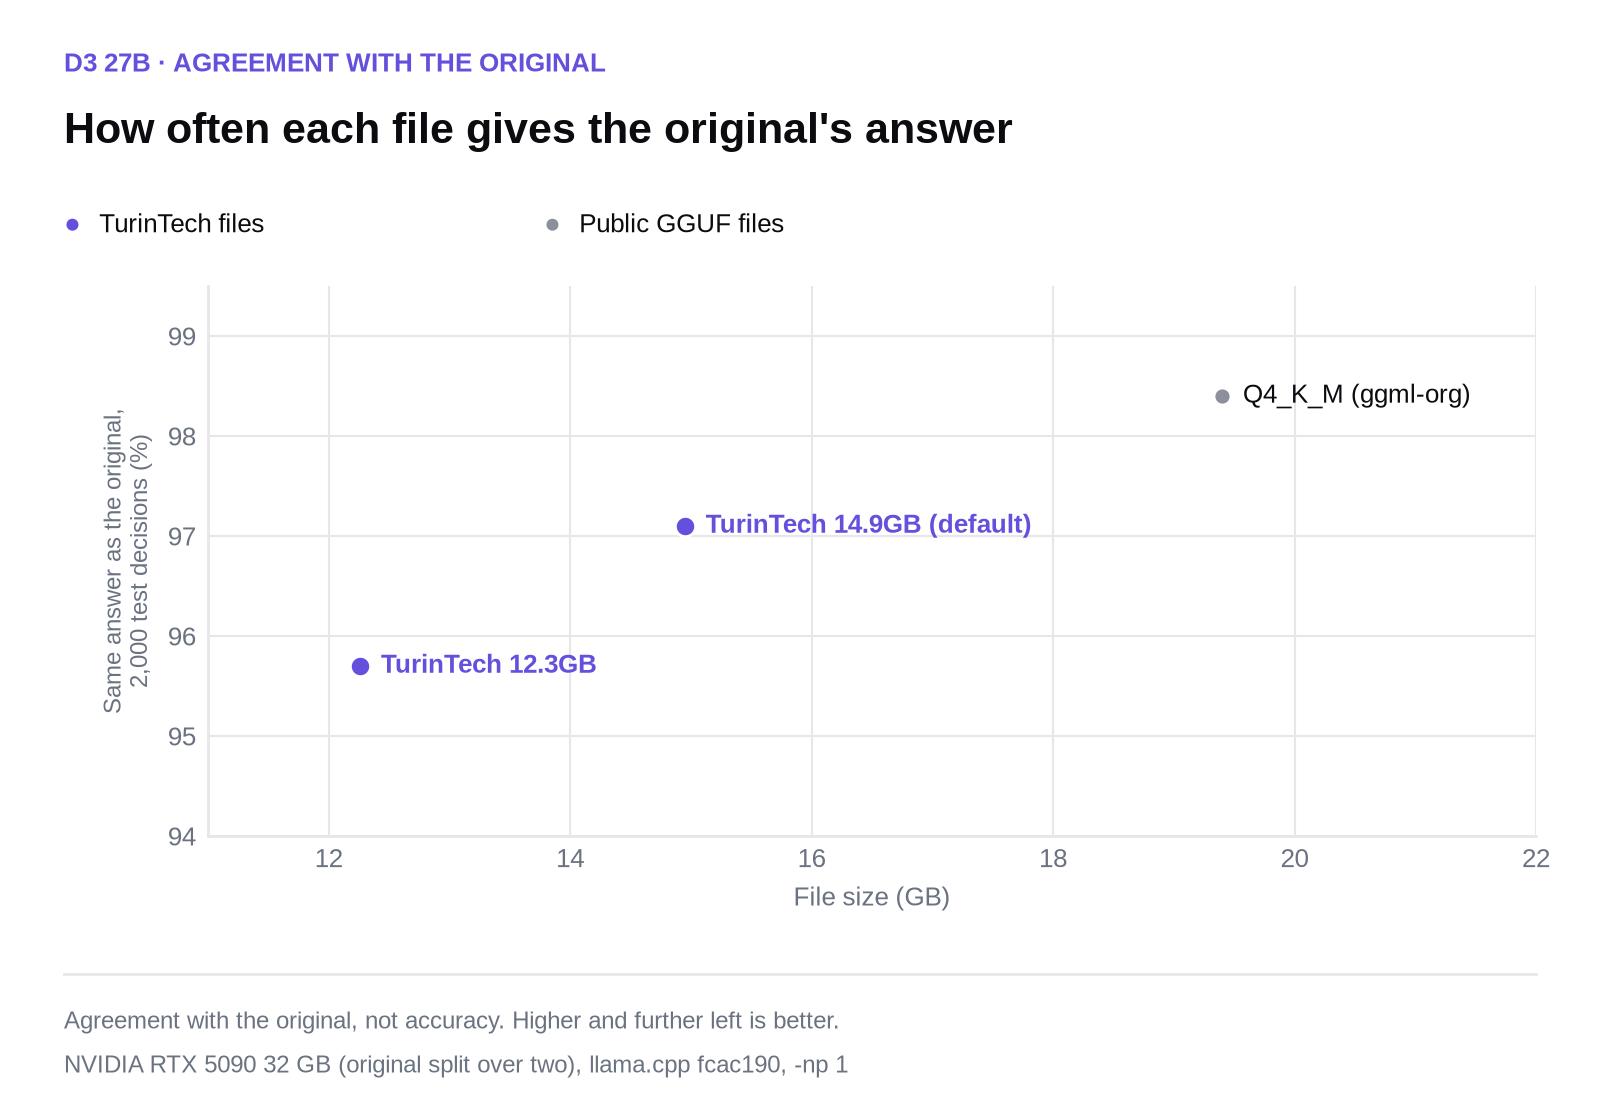
The second file, d3-27B-Artemis-12.3GB.gguf, is 12.26 GB and needs 14.1 GiB for text, so it should fit a 16 GB GPU. It agrees with the original on 95.7% of the test decisions, with accuracy 0.30 points lower, and changed no confident answer.
d3-flash 9B
The d3-flash Artemis GGUF default, d3-flash-Artemis-4.9GB.gguf, is 4.87 GB, 73% smaller than the original. It gives the original's answer on 94.5% of the test decisions and changed none of the 821 answers the original was more than 80% sure of. Its accuracy on those decisions is 72.25% against the original's 71.10%. The card puts the 95% range of that gain at 0.1 to 2.1 points and says it should not be read as an improvement on other tasks. On the image questions it agrees 95.8% of the time.
On an RTX 5090 it needs 6.1 GiB of GPU memory for text and 8.3 GiB with images, against 17.0 GiB for the original, so it should fit an 8 GB GPU for text.
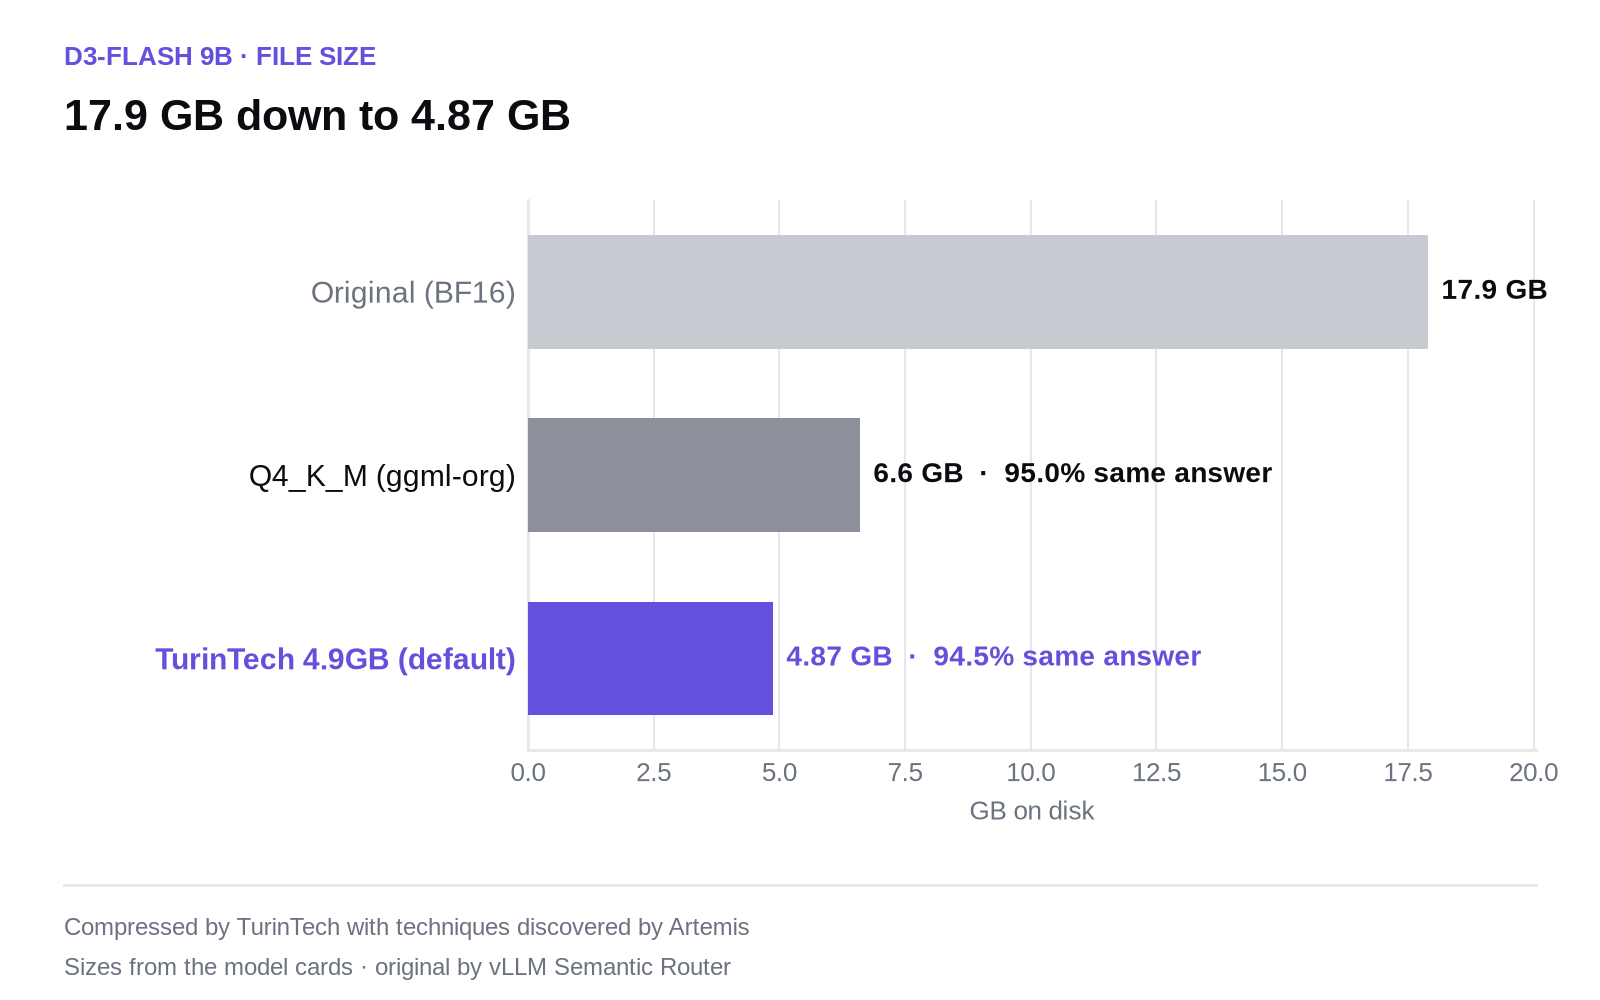
The ggml-org Q4_K_M, at 6.60 GB, agrees slightly more often: 95.0% on the test decisions and 96.7% on images. Our default is 26% smaller. On the held-out decisions the two agree with the original about equally often (94.7% for ours, 94.3% for the Q4_K_M), but the Q4_K_M is 2.8 points less accurate than the original there, where ours matches it. On the benchmark sample both agree 96.3% of the time.
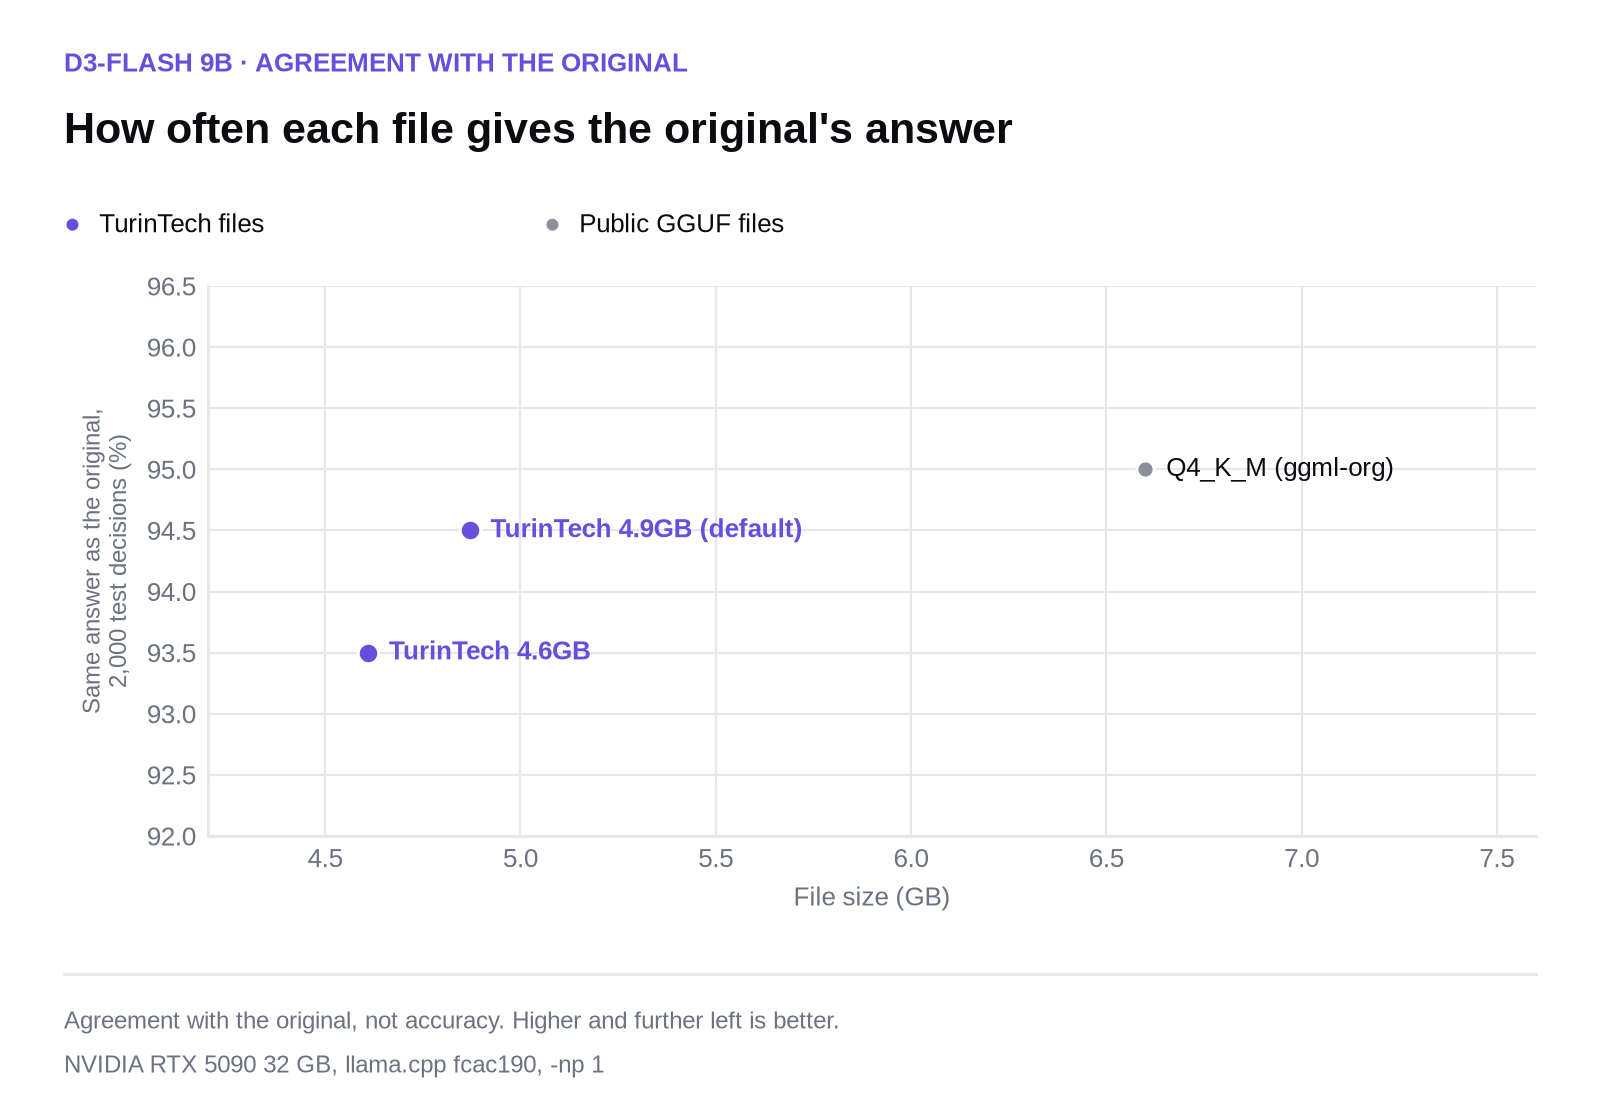
The smaller file, d3-flash-Artemis-4.6GB.gguf, is 4.61 GB and agrees 93.5% of the time. It saves only 0.1 GiB of GPU memory and changed 2 of the 821 answers the original was more than 80% sure of, so the default is the better choice for most uses.
How it was tested
Every file was compared with the BF16 original and with ggml-org's Q4_K_M at identical llama.cpp settings (commit fcac190, one request at a time), each file on one NVIDIA RTX 5090. The checks were 2,000 decisions from the test split of typed-decisions, 1,000 held-out decisions, a 300-item sample of the Decision Index benchmarks, 330 image questions from CV-Bench, RealWorldQA and BLINK, shuffled answer options, the longest inputs and repeat runs. Video was not tested.
Shuffling the answer options changes 3.1% of d3's own answers and 5.1% of d3-flash's. Our files change 3.9 to 4.1% for d3 and 6.6 to 8.4% for d3-flash, and the Q4_K_M files 3.8% and 6.7%. Repeat runs gave identical answers for every file. d3 answers each question in a request on its own, and sending the questions one per request gave the same answers.
Run it
hf download turintech/d3-flash-Artemis-GGUF d3-flash-Artemis-4.9GB.gguf --local-dir .
llama-server -m d3-flash-Artemis-4.9GB.gguf --port 8080 -c 16384 -ub 4096 -b 4096 -np 1
The files need llama.cpp release b11572 (12 October 2026) or newer. Keep -ub 4096 -b 4096, because d3 reads the whole prompt in one batch and rejects longer inputs. Keep -np 1 as well: with several parallel slots, llama.cpp can change a d3 answer when a shorter request shares the batch (llama.cpp issue #30402, open on 14 October 2026). For images, add ggml-org's vision projector with --mmproj and raise the batch to 8192. The model cards for d3 and d3-flash have the commands, the full test tables and checksums.
These are independent conversions, not affiliated with or endorsed by the vLLM Semantic Router Team, and the credit for d3 and d3-flash belongs to them. The files were compressed by TurinTech with techniques discovered by Artemis. The rest of the Artemis Edge collection is on Hugging Face. Versions tuned on a team's own decisions or built for specific hardware are available on request: book a call.