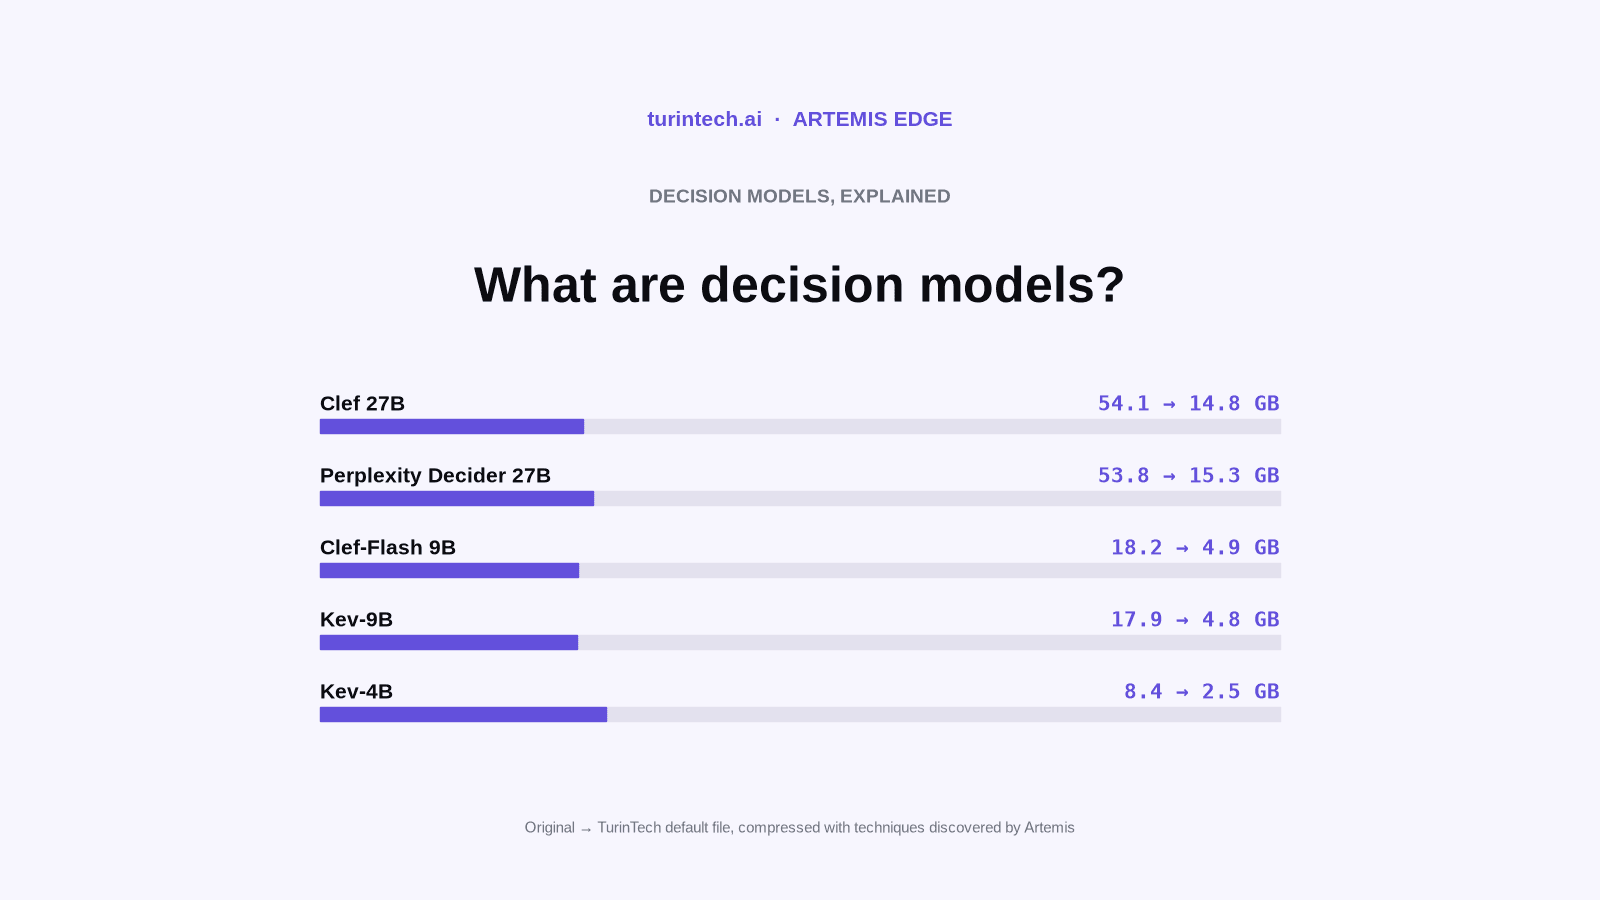
pplx-decider is Perplexity's open decision model. As of 13 October 2026, our files are the only public GGUFs of it that run on stock llama.cpp. If decision models are new to you, start here.
The original
Perplexity released pplx-decider on 1 October 2026 as an open-weight 27B model under Apache 2.0, post-trained from Qwen3.8-27B. It reads text or images and gives a probability for each allowed answer to yes or no, pick-one and score questions. Perplexity also serves it through its own API.
On 5 October Perplexity published pplx-decider-v1.1-27b, the version we compressed. On the same backbone, v1.1 raised its Decision Index score from 56.4 to 61.56. Perplexity puts most of the gain down to letting the model's full-attention layers see the whole input in both directions and to training on more data. It credits a large part of the improvement to Damien Sileo's tasksource collection. Perplexity announced that v1.1 scored highest on the new Decision Index 0.3.
Getting it into llama.cpp
The original is packaged differently from a normal language model. Its card explains that it ships with a separate decision head instead of the usual output layer, and that the full-attention layers must run in a non-causal mode to reproduce the evaluated behaviour. When we checked again on 13 October 2026, the only other public GGUF repository of the model was Livesport's, published on 8 October with Q5_K_M and Q8_0 files. Those files need Livesport's own bridge binary and Python server, so they do not run on stock llama-server.
Our files load in stock llama.cpp from 9 October 2026 and answer through the standard /v1/systemone endpoint. Perplexity does not publish a llama.cpp vision projector either, so the repository includes one converted from the original weights, in BF16 and in a smaller 0.63 GB Q8_0 version. With the original model, the Q8_0 projector gives the same answer as the BF16 one on 98.8% of our image questions.
What we made
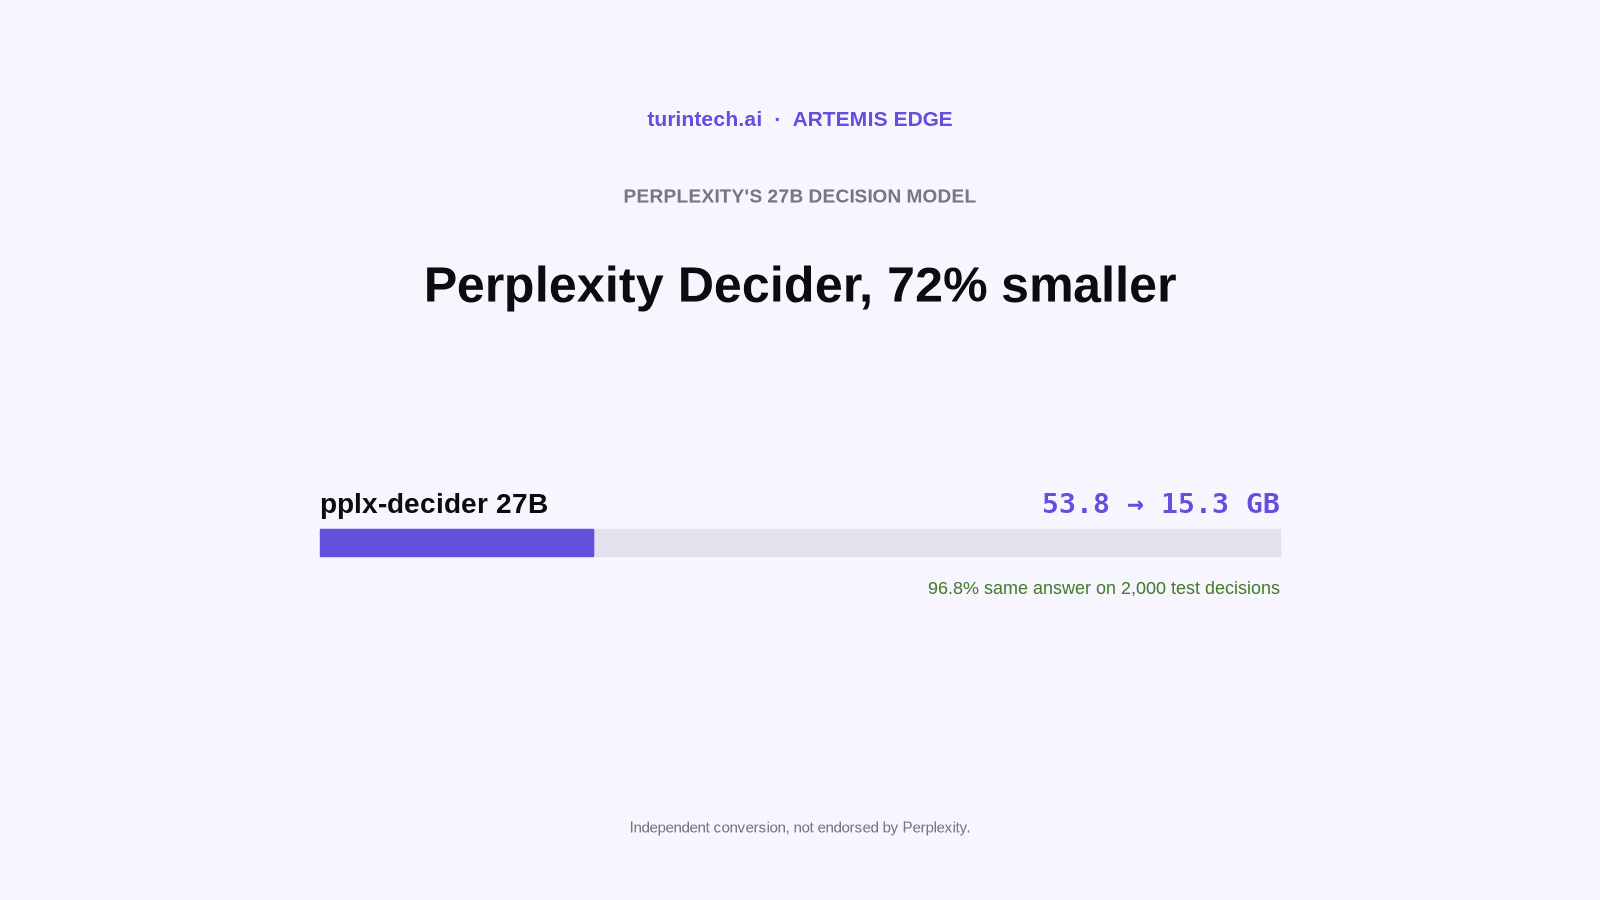
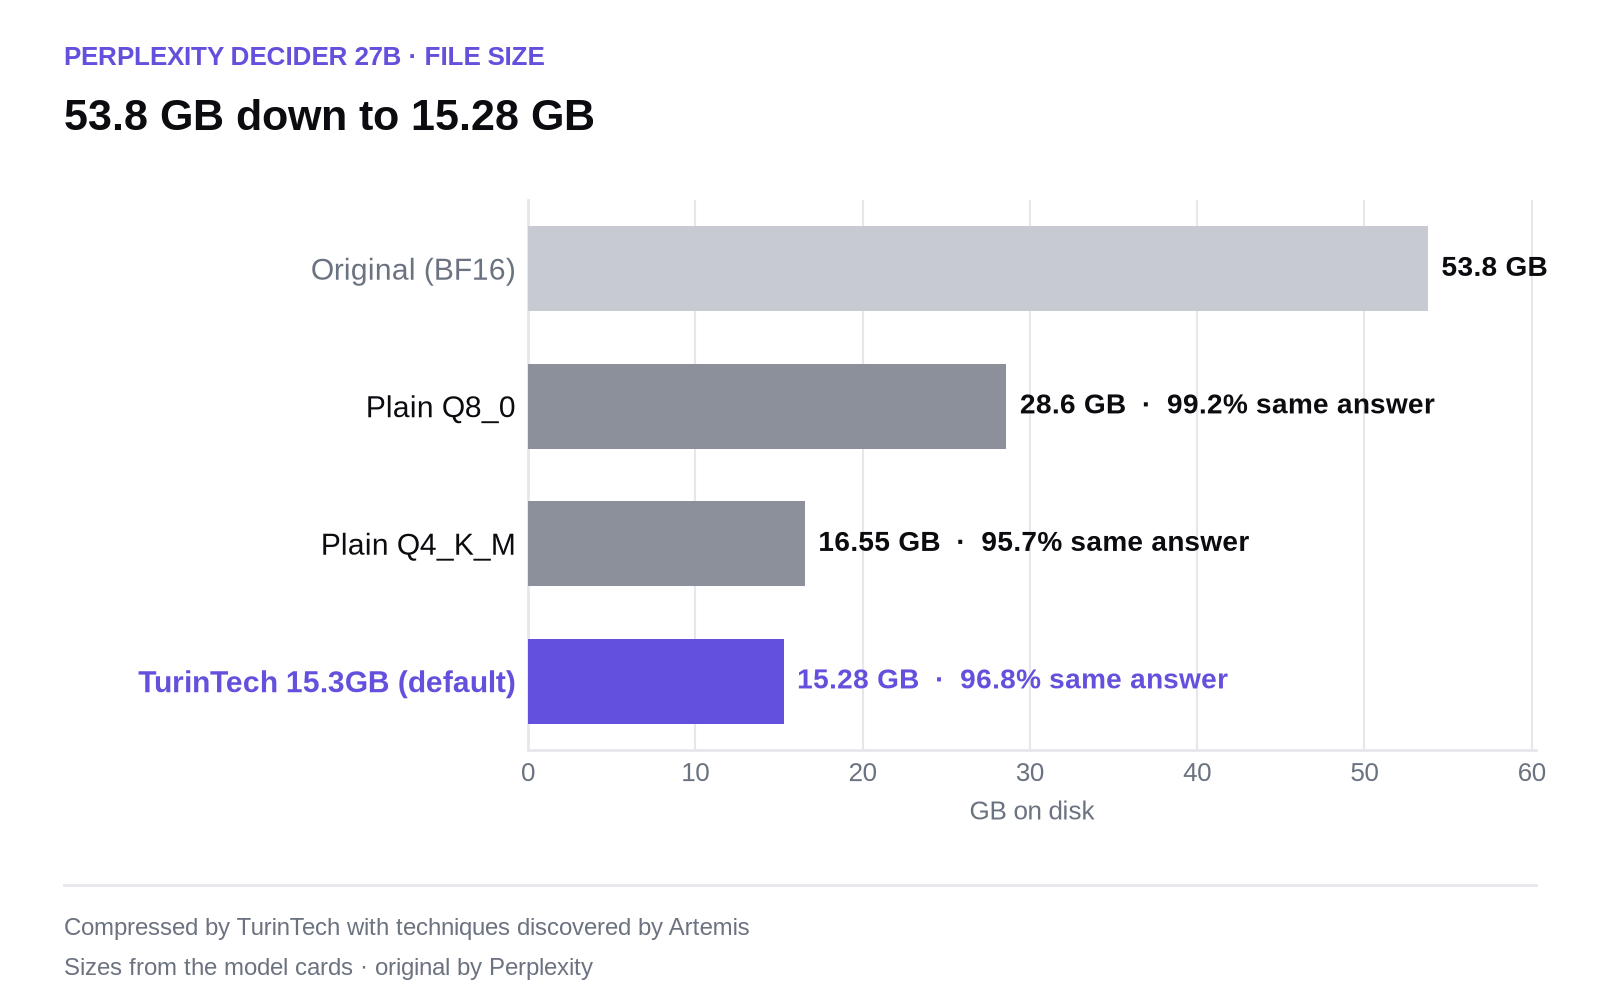
The pplx-decider-27B Artemis GGUF repository has two files. The default, pplx-decider-27B-Artemis-15.3GB.gguf, is 15.28 GB, 72% smaller than the original's 53.8 GB.
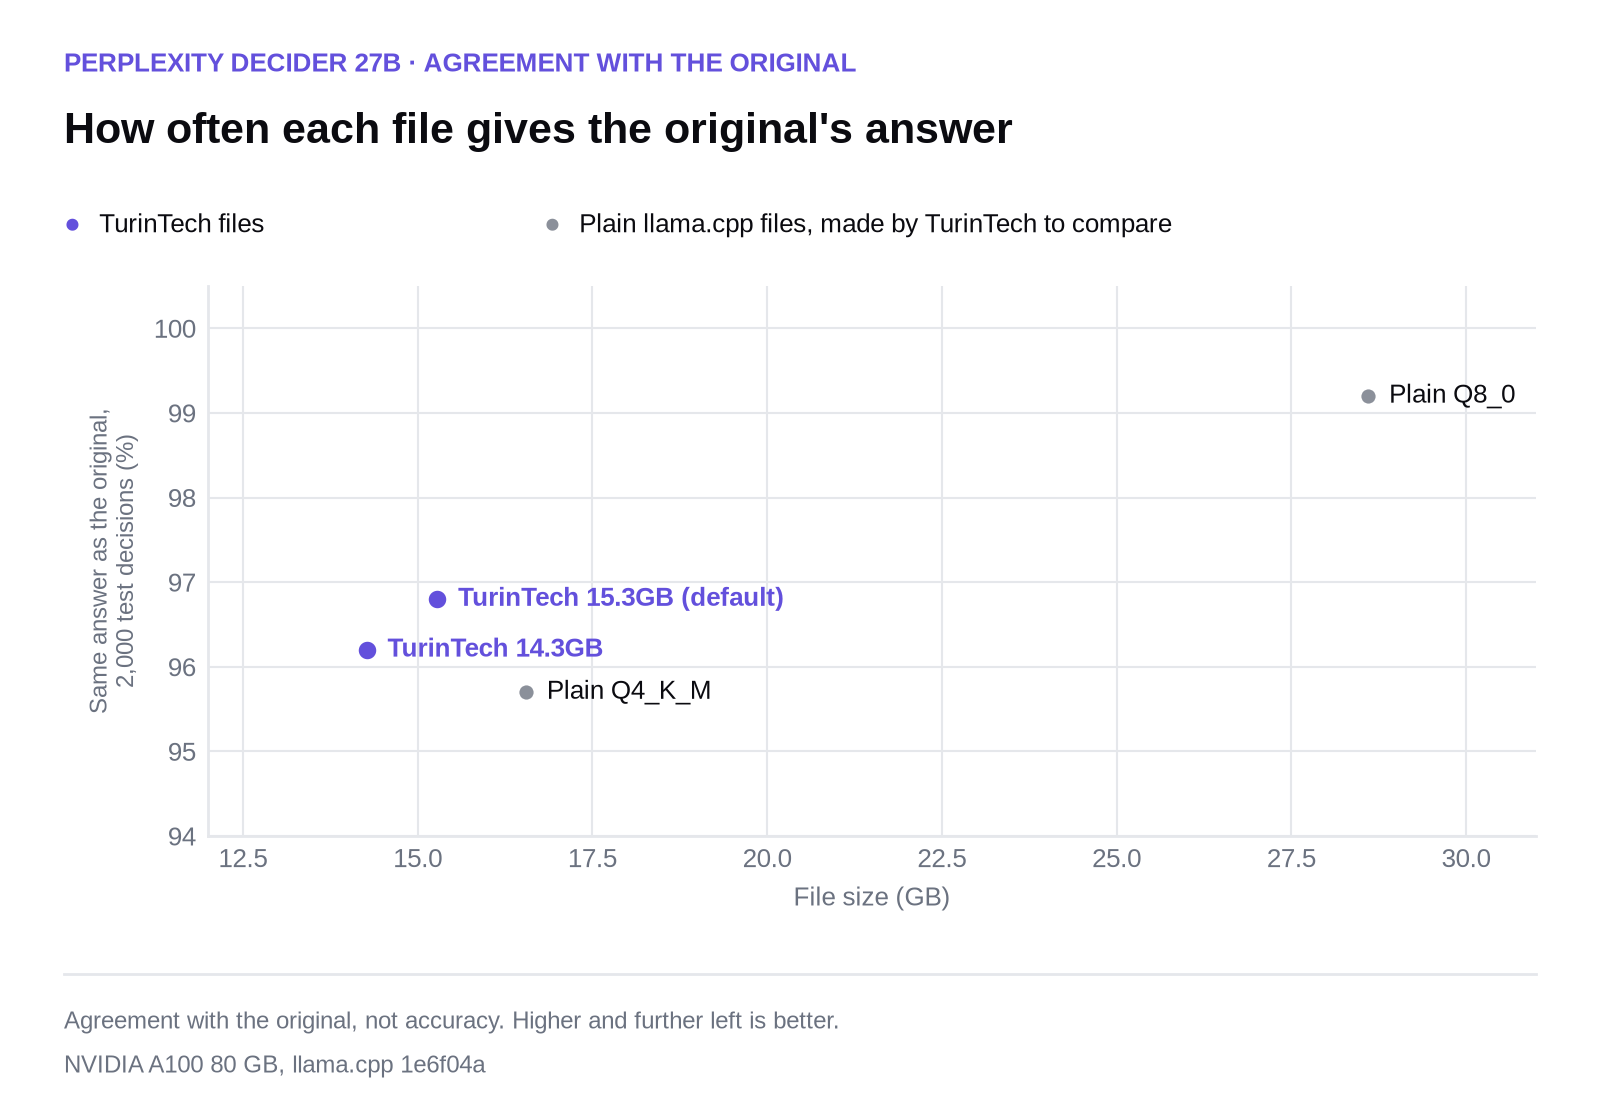
On the 2,000 test decisions, run on an NVIDIA A100, it gives the original's answer 96.8% of the time, and its accuracy is 70.8% against the original's 70.5%. On an A100 it changed no answer the original was more than 80% sure of, in text or images. On 330 image questions it agrees 97.6% of the time. On the A100 it needs 16.6 GiB of GPU memory for text, against 50.8 GiB for the original, so it should fit a 24 GB GPU.
| File | Size | Same answer as the original | Accuracy change (points) | Confident answers changed |
|---|---|---|---|---|
| Original, BF16 | 53.8 GB | reference | reference | |
pplx-decider-27B-Artemis-15.3GB (default) | 15.28 GB | 96.8% | +0.3 | 0 |
pplx-decider-27B-Artemis-14.3GB | 14.27 GB | 96.2% | +0.7 | 0 |
How it compares
With no stock-compatible public file to compare against, we made plain Q8_0 and Q4_K_M files from the original with llama.cpp's standard llama-quantize tool and ran them through the same tests. The Q8_0 (28.6 GB) gives the original's answer 99.2% of the time and the Q4_K_M (16.55 GB) 95.7%.
Our two files are 1.3 to 2.3 GB smaller than that Q4_K_M and closer to the original on the test decisions (96.8% and 96.2% against 95.7%) and on the held-out ones (97.3% and 96.0% against 94.9%). The Q4_K_M is closer on the 300-item benchmark sample, 98.0% against 96.0% for our default.
The original is itself sensitive to the order of the options: shuffling them changes 8.4% of its own answers. Our files stay close to that (9.6% for the default, 7.9% for the 14.3 GB file).
How it was tested
Every file was compared with the BF16 original at identical llama.cpp settings (commit 1e6f04a) on one NVIDIA A100 80 GB, on 2,000 decisions from the test split of typed-decisions, 1,000 held-out decisions, a 300-item sample of the Decision Index benchmarks and 330 image questions. Repeat runs gave identical answers on the A100.
We repeated the text checks on an NVIDIA RTX 5090. Results were within 1.5 points of the A100 on every check: the default agreed with the original on 96.5% of decisions. On that GPU it changed one answer the original was more than 80% sure of (at 84%), and a repeat run matched 99.6% of its answers, where on the A100 every answer matched.
Run it
hf download turintech/pplx-decider-27B-Artemis-GGUF pplx-decider-27B-Artemis-15.3GB.gguf --local-dir .
llama-server -m pplx-decider-27B-Artemis-15.3GB.gguf --port 8080 -c 16384 -ub 4096 -b 4096
For images, download mmproj-pplx-decider-27B-BF16.gguf from the same repository and add --mmproj. The model card has the commands, the full test table and checksums.
This is an independent conversion, not affiliated with or endorsed by Perplexity, and the credit for pplx-decider belongs to Perplexity and the authors of the data it was trained on. The files were compressed by TurinTech with techniques discovered by Artemis. The rest of the Artemis Edge collection is on Hugging Face. For a version tuned on your own decisions or built for your hardware, book a call.