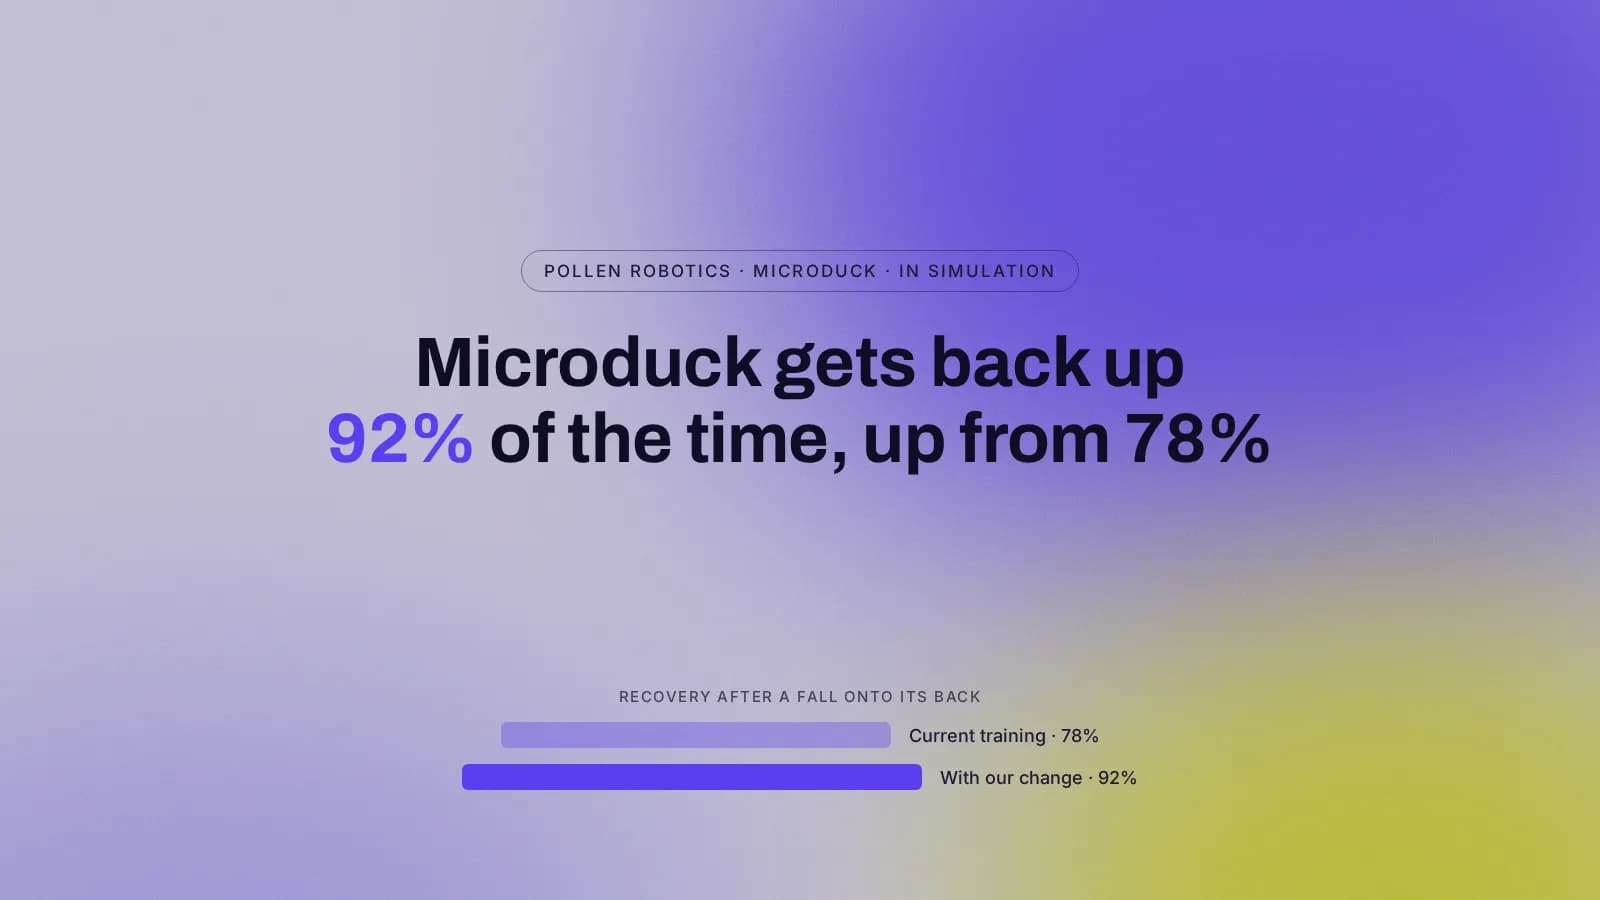
Microduck PR #54 changes one rule in how the robot's walking policy is trained. In simulation, falls onto its back now end in a recovery 92–94% of the time instead of 78–79%, and the robot is upright in 1.5–1.7 seconds instead of 2.5. Walking is unchanged. The work was done with Artemis by Mina and Matthew on our team, and the pull request is open for the maintainers to review.
The robot
Microduck is a 25 cm, 780 g, open-source, two-legged robot from Pollen Robotics, part of Hugging Face. It has 15 motors, a camera and a depth sensor, and it walks, roller-skates, picks things up with its beak and gets back up after many common falls. Here it is in Pollen Robotics' launch video:
Its behaviours are trained with reinforcement learning in simulation and then run on the real robot. The training code, microduck_rl, is public, which is where our change lives. A small robot that walks will fall over, so what matters is how quickly and reliably it gets up again.
Our simulation
This is the side-by-side from our pull request, zoomed in on the robot. The same seed is trained for 2,000 iterations, then let loose in free play with pushes that knock it over. The current training is on the left and our change is on the right.
The problem
The maintainers had already written down the symptom: after a real fall onto its back, the robot convulsed instead of rising. In simulation, face-up landings after a push recovered 58–77% of the time, while the same robot spawned lying face up recovered almost every time.
The policy learns in two ways at once. Reinforcement learning (PPO) rewards it for getting up, and a cloning step pulls it towards a separate stand-up expert. The cloning step applied to every frame tilted more than 35°. That expert had only been trained from calm starting poses and had never seen the leg positions a real tumble leaves behind. Because cloning runs after PPO in each iteration, whatever PPO learned during a tumble was undone straight away.
So adding more reward would not help. The fix was in what the robot was being asked to copy, and when.
The change
In distill.py, a fallen frame is now cloned only while the body is rotating slower than 3 radians per second. While the robot is still tumbling, PPO and the existing recovery rewards are in charge. Once the body has settled, the expert teaches the get-up.
A natural Microduck tumble runs at 3.5–5.5 rad/s, and a slow push-up stays well under 3, so the threshold separates the two cleanly. The share of fallen frames being cloned drops from 25% to 6%. The change is 15 lines added and one removed, in one file, and the threshold is a config value.
The receipts
Every run starts from the published VelStand policy, with 4,096 simulated environments and every training curriculum at its final, hardest stage. Baseline and change use the same seeds. Ranges are the lowest and highest across seeds.
| Setting | Recovered after a fall onto its back | Time to stand |
|---|---|---|
| Flat ground, 4,000 iterations, 3 seeds | 0.78–0.79 → 0.92–0.94 | 2.5 → 1.5–1.7 s |
| Flat ground, 600 iterations, 10 seeds | 0.77–0.79 → 0.88–0.92 | 2.4–2.6 → 1.6–1.9 s |
| Rough ground with backlash, 600 iterations, 3 seeds | 0.74–0.76 → 0.85–0.86 | 2.5 → 1.8–1.9 s |
No seed of the baseline overlaps any seed of the change on a recovery metric, and the gap grows with longer training. Recovery from falls onto the side improves too. Recovery from face-down falls, servo stalls and impact forces on the head and body are unchanged. Walking speed tracking, measured without pushes, is the same within noise across six seeds.
What it does not cover
All of this is in simulation. The change has not been tested on a physical robot, and that is the next step for the maintainers to judge. The pull request is open and has not yet been reviewed.
Most of our public work so far is on inference speed. This one is different: the measure is how often a robot gets up, and the proof is a set of paired training runs. The approach is the same, though. Find the narrow rule that holds the result back, change it, and show with repeated measurements that nothing else got worse.