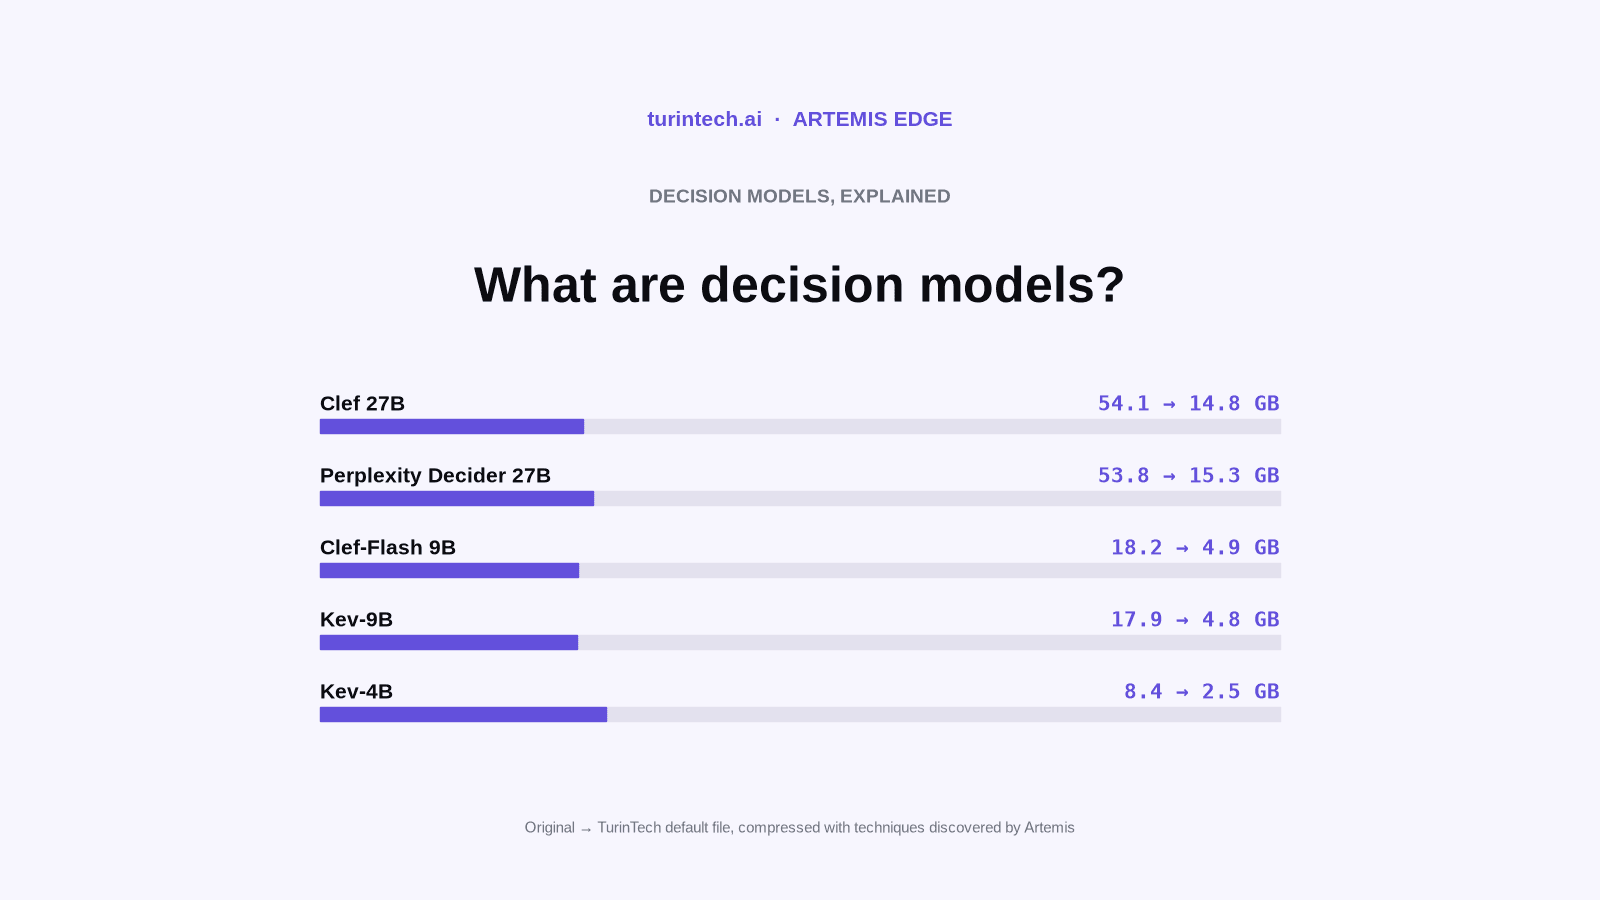
Kev is the open decision-model family built by Jared Palmer. It is published with its training code and recipe, so anyone can fine-tune it on their own labels. We compressed the 9B and 4B sizes. Of all the models in this release, Kev is where the public files compare best: the public Q4_K_M files keep slightly more agreement with the originals, and ours are smaller. If decision models are new to you, start here.
The original
Jared Palmer started Kev because he wanted the interface of TypeSafe's Jev with weights he could run and fine-tune himself, as he wrote in Introducing Kev. Kev uses the same /v1/systemone request format, so applications built for Jev can switch by changing the endpoint and the model name. The first prototype was a 0.5B model that could be trained and run on a MacBook Pro; Kev 1.0, published on 1 October 2026, has four sizes from 0.8B to 27B under Apache 2.0, with the code, training recipe and evaluations on GitHub.
Each Kev model is a Qwen3.5 base with a small adapter and a "pointer head" that scores the answer options it is given. The Kev-9B card is unusually thorough: it reports results on held-out datasets, calibration error, long-document limits and where the model is weak, such as date arithmetic and knowledge-heavy exams. It is aimed at developers who classify, route or check documents and want probabilities they can put a threshold on. Kev-4B was one of the models llama.cpp supported on the day it added the /v1/systemone endpoint (Hugging Face blog).
What we made
| Model | Original | Our default file | Smaller by | Same answer as the original | Confident answers changed | Measured on |
|---|---|---|---|---|---|---|
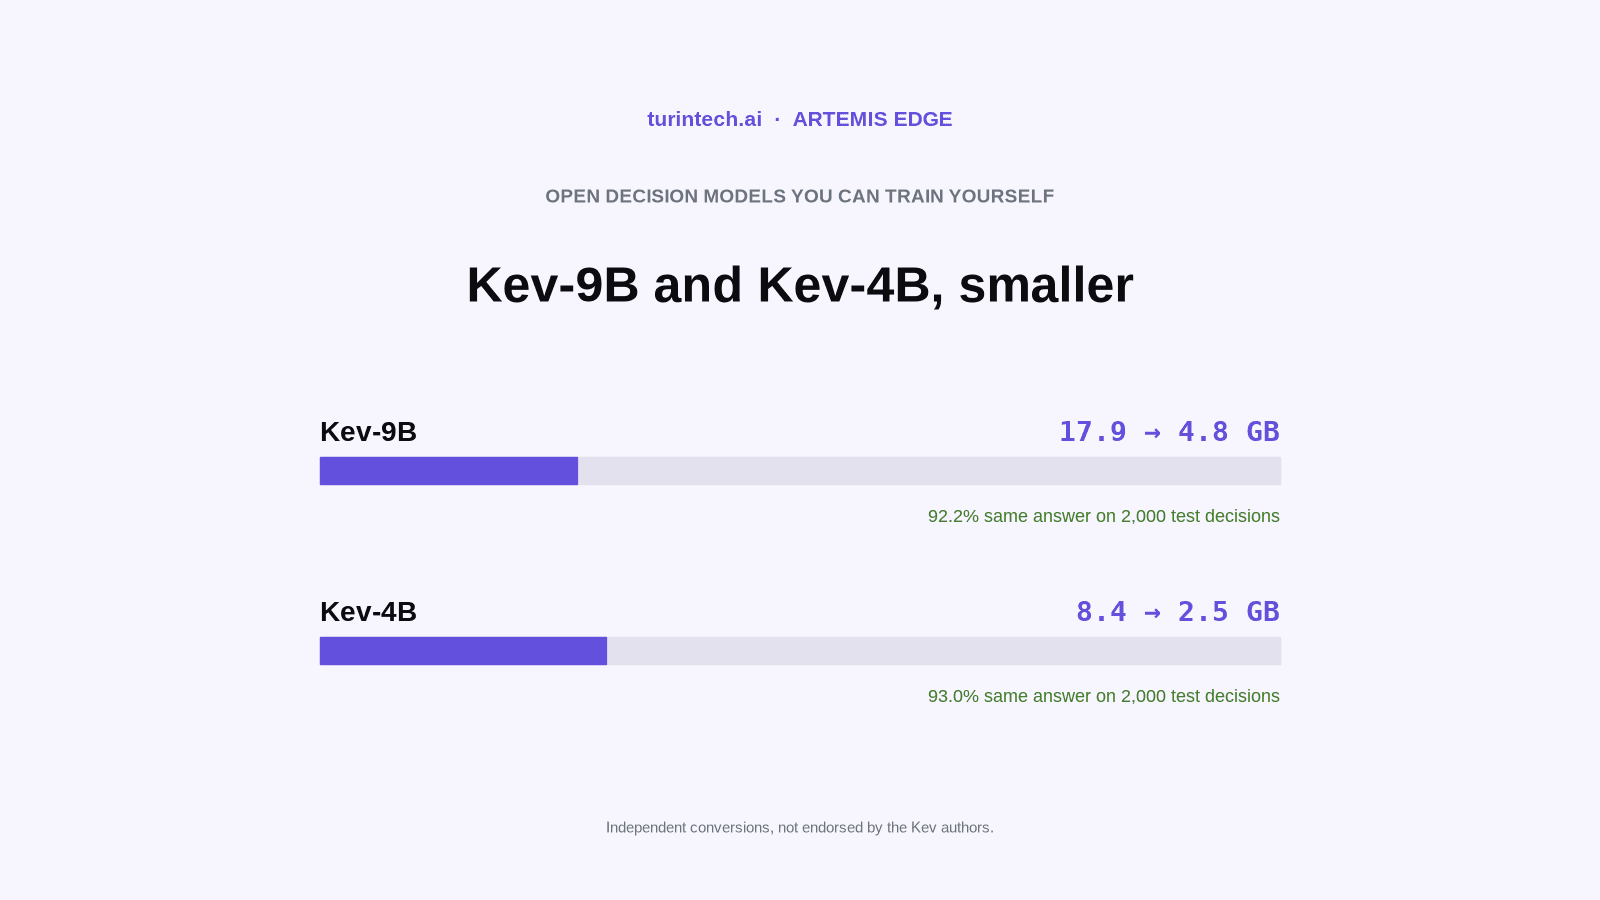
| Kev-9B | 17.9 GB | 4.78 GB | 73% | 92.2% | 0 | NVIDIA A100 |
| Kev-4B | 8.43 GB | 2.54 GB | 70% | 93.0% | 0 | NVIDIA RTX 5090 |
Agreement is the share of 2,000 test decisions on which the file gives the original's answer. "Confident answers changed" counts answers the original was more than 80% sure of that the file changed.
Kev-9B
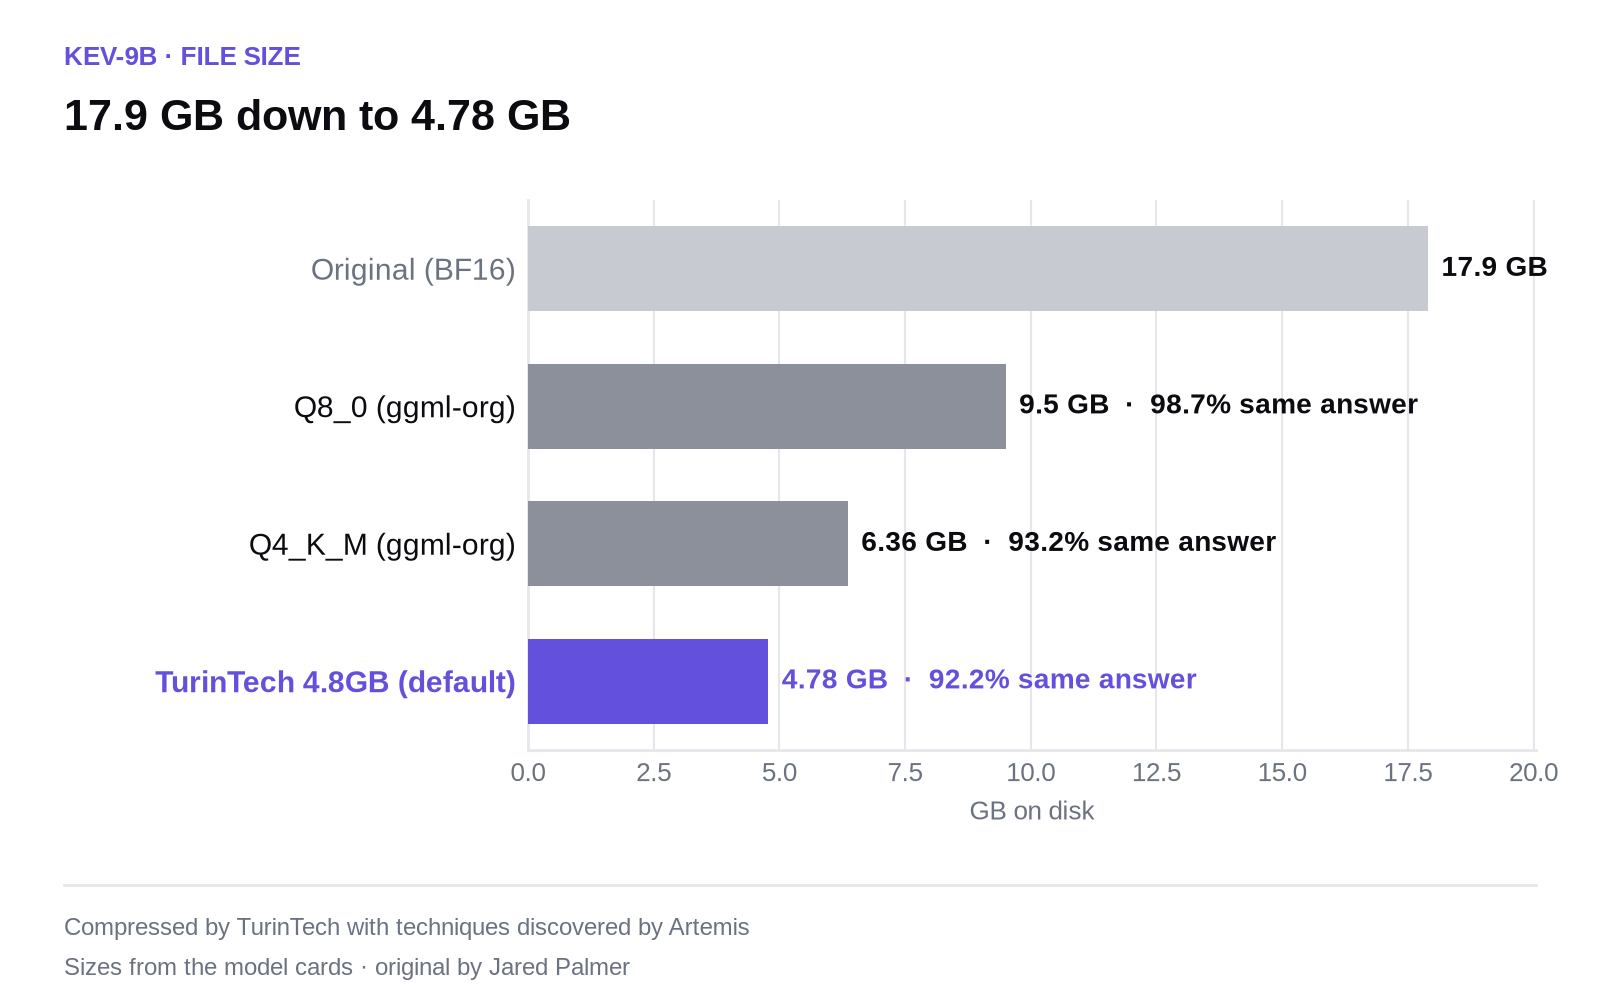
The Kev-9B Artemis GGUF default is 4.78 GB. On an NVIDIA A100 it gives the original's answer on 92.2% of the test decisions and on 92.8% of the held-out ones. Accuracy is 67.8% against the original's 69.0%, about a point lower.
The ggml-org Q4_K_M is 6.36 GB and closer to the original: 93.2% on the test decisions and 94.3% on the held-out ones, with accuracy 0.6 points lower. Our file is 25% smaller than it. The ggml-org Q8_0 (9.5 GB) agrees 98.7% of the time. Neither of the public files nor any of ours changed a confident answer.
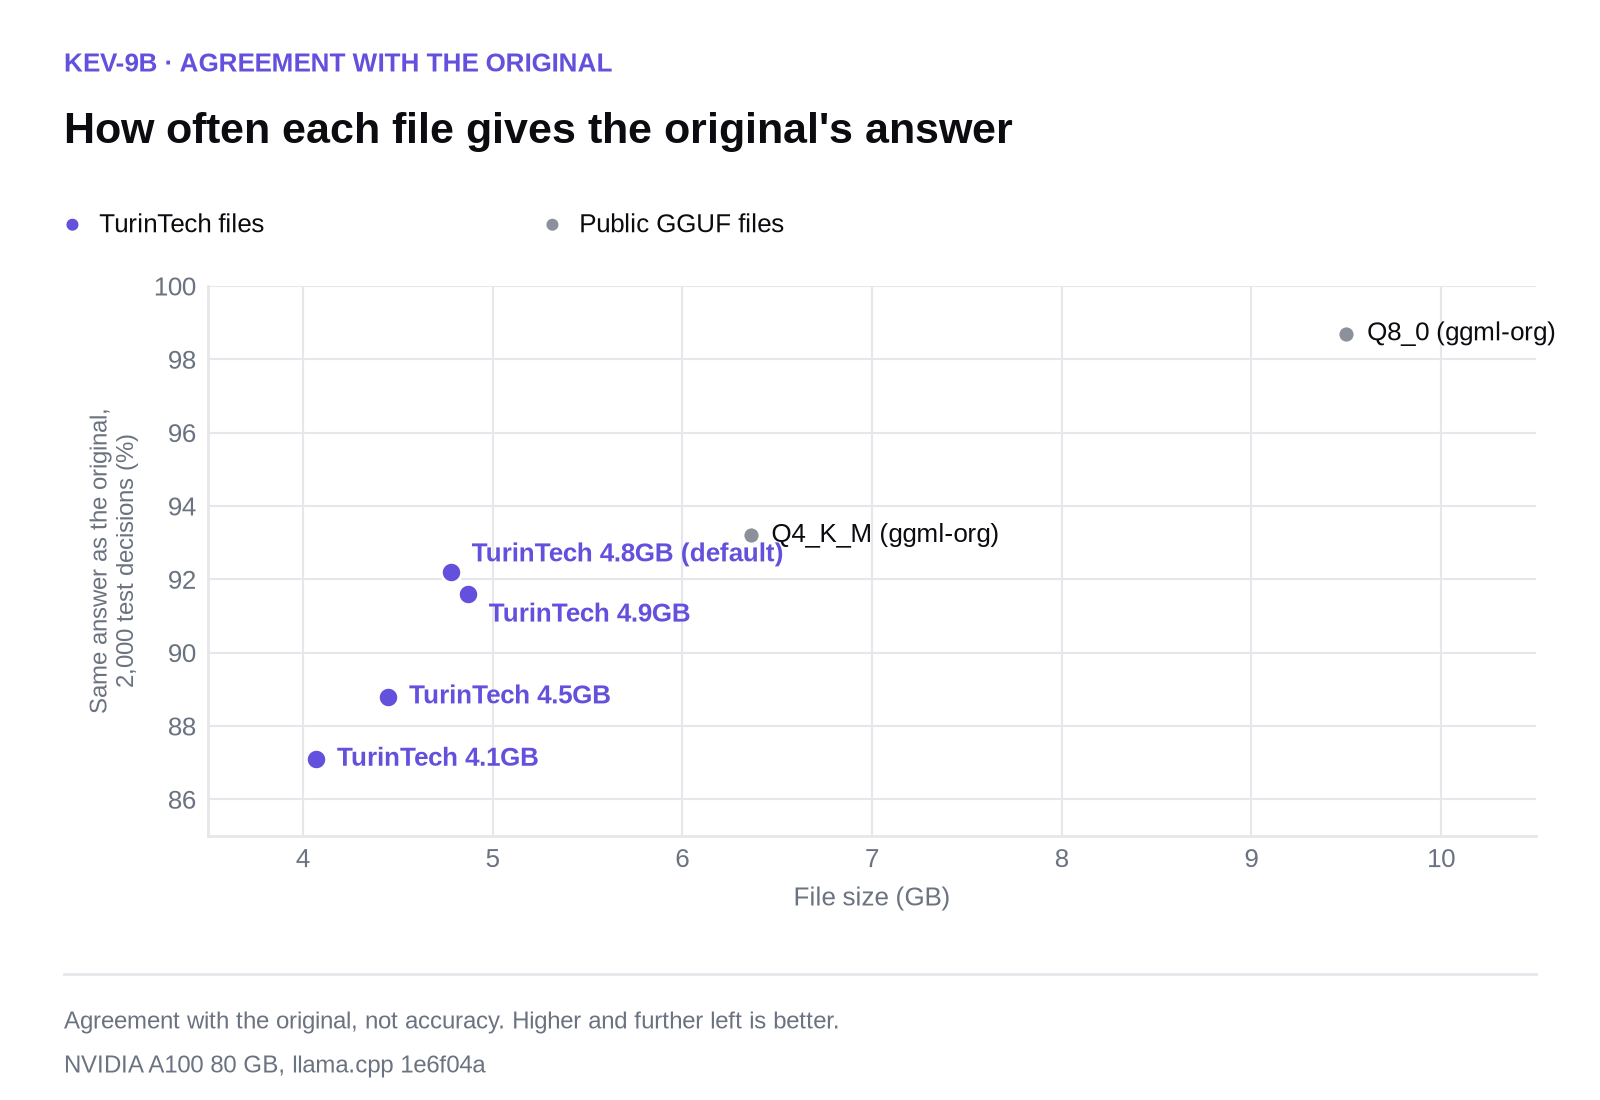
The repository has three other files, from 4.07 to 4.87 GB, which agree 87.1 to 91.6% of the time; the smallest is about 2 to 3.5 points lower in accuracy. The card also notes that the 4.8 GB file was chosen partly on the held-out decisions, so for that file they act as a validation set and are not untouched. On the A100 the 4.8 GB file needs 9.1 GiB of GPU memory, against 20.0 GiB for the original.
A real run, recorded live on a desktop CPU (AMD Ryzen 9 9950X). The original Kev-9B and Kev-9B-Artemis-4.8GB.gguf choose an agent's next tool from the same synthetic traces and agree on all three steps. Both are unsure on the middle one, at 46.3% and 45.2%.
Kev-4B
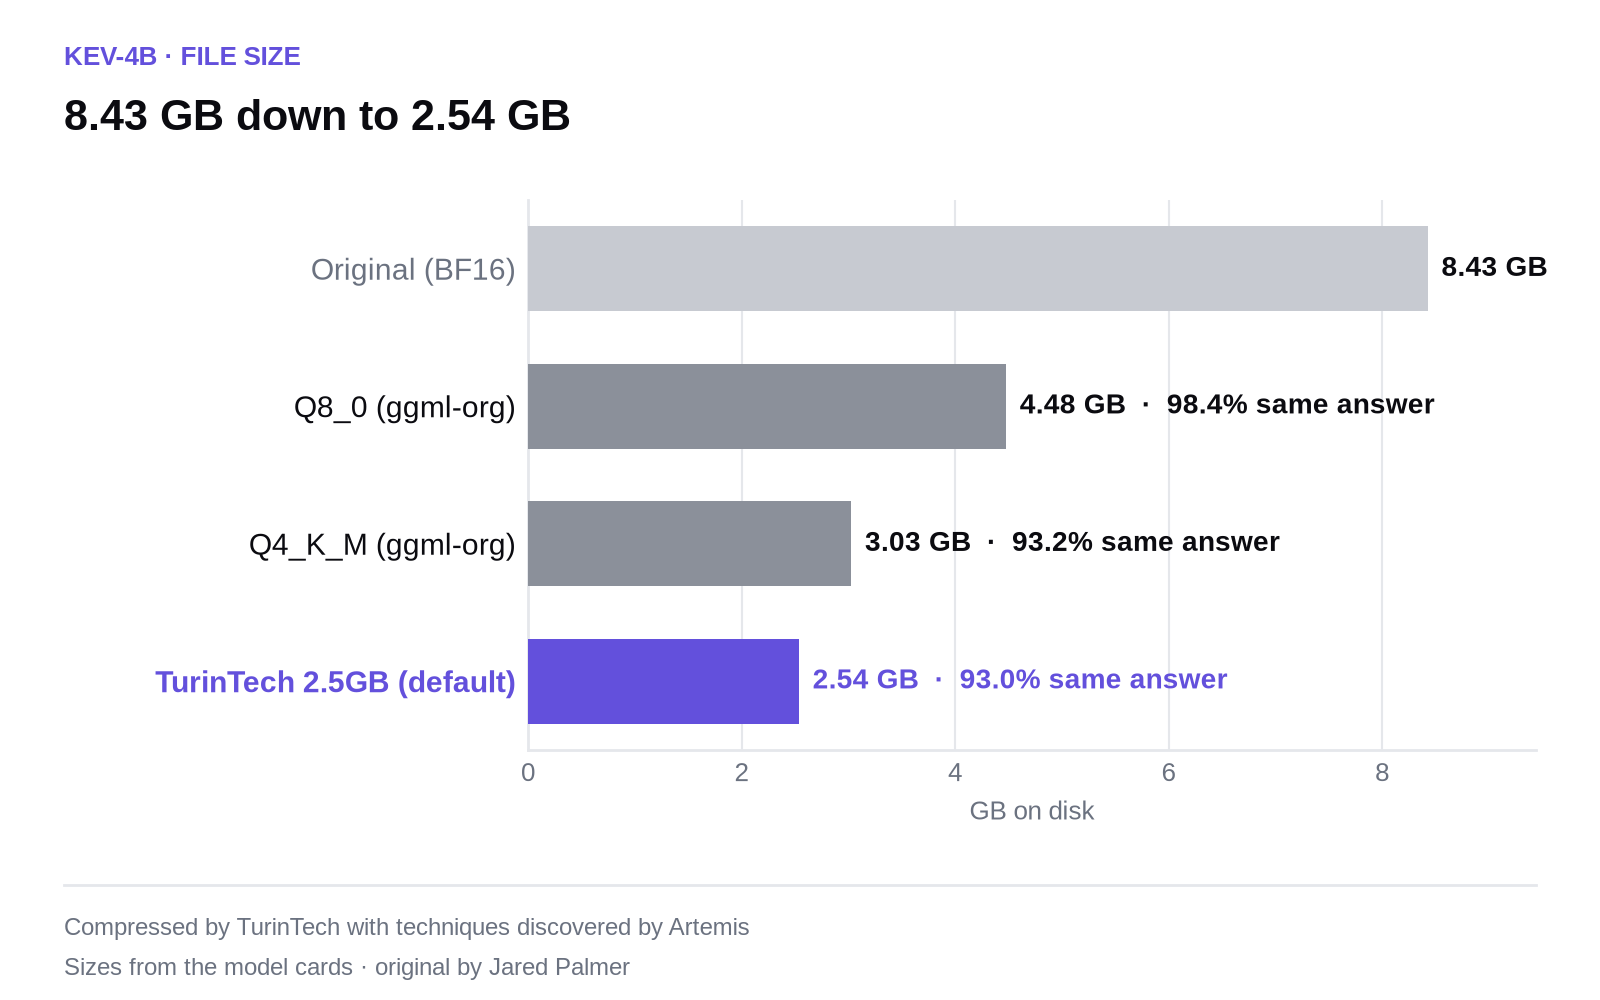
The Kev-4B Artemis GGUF default is 2.54 GB. On an NVIDIA RTX 5090 it gives the original's answer on 93.0% of the test decisions, close to the ggml-org Q4_K_M's 93.2%, and its accuracy on them is unchanged (66.8% for both). It changed none of the 244 answers the original was more than 80% sure of.
The 3.03 GB Q4_K_M does better away from the test split. On held-out decisions it agrees 94.0% of the time against our 92.7%, with accuracy 0.1 points lower than the original against our 1.7. On the benchmark sample it agrees 96.0% against our 94.0%. Our file is 16% smaller.
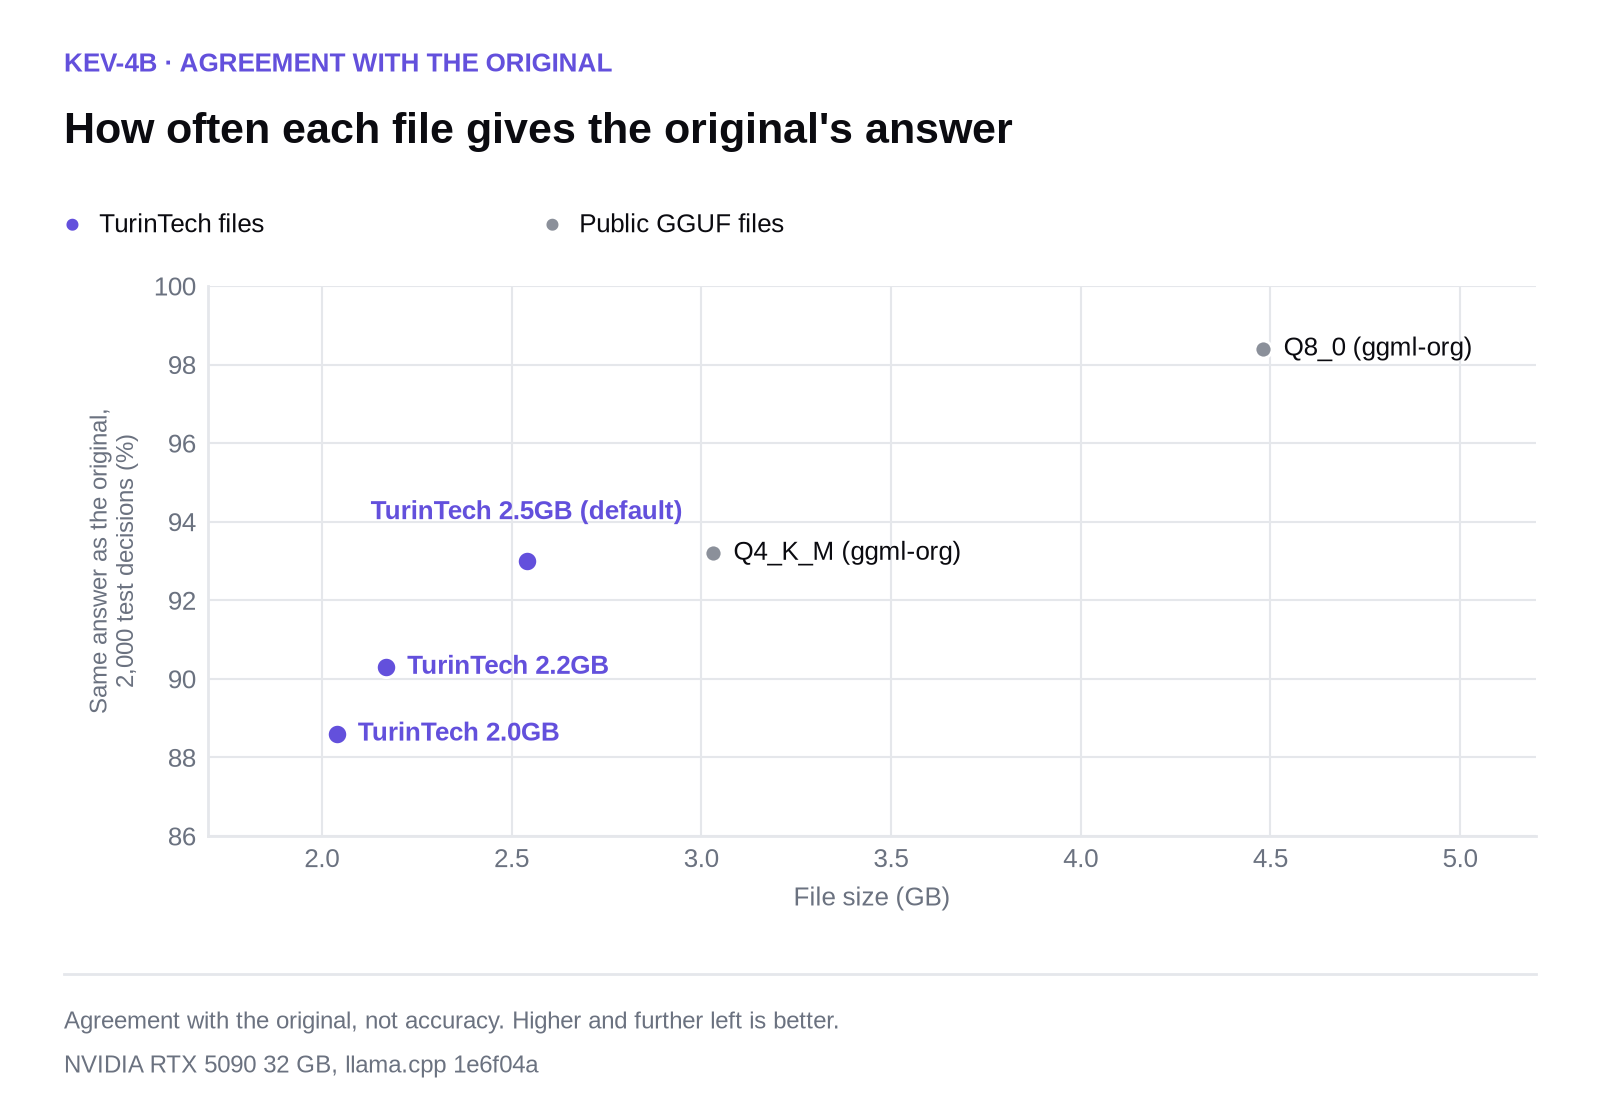
Kev answers each question in a request separately, and the original gives the same answers whether questions arrive together or one per request. Our Kev-4B files change 25 to 35 of the 2,000 answers when the questions are split up, so comparisons should keep the request shape fixed.
A real run, recorded live on a desktop CPU (AMD Ryzen 9 9950X). It uses our smallest Kev-4B file, Kev-4B-Artemis-2.0GB.gguf, which agrees with the original on 88.6% of the test decisions, and not the 2.5 GB default. On these three synthetic support tickets both files pick the same team.
How it was tested
Every file was compared with the BF16 original and the public ggml-org files at identical llama.cpp settings (commit 1e6f04a): Kev-9B on one NVIDIA A100 80 GB, Kev-4B on one NVIDIA RTX 5090. The checks were 2,000 decisions from the test split of typed-decisions, 1,000 held-out decisions, a 300-item sample of the Decision Index benchmarks, shuffled answer options and repeat runs. Kev is text only, so there were no image tests.
Both originals are sensitive to option order: shuffling changes 9.8% of Kev-9B's own answers and 8.6% of Kev-4B's. Our files change 9.5 to 12.4% of theirs, and the public Q8_0 and Q4_K_M files 8.9 to 11.4%. Repeat runs were identical for every file.
Run it
hf download turintech/Kev-4B-Artemis-GGUF Kev-4B-Artemis-2.5GB.gguf --local-dir .
llama-server -m Kev-4B-Artemis-2.5GB.gguf --port 8080 -c 16384 -ub 4096 -b 4096
The files need llama.cpp from 9 October 2026 or newer. The model cards for Kev-9B and Kev-4B have every file, the full test tables and checksums.
These are independent conversions, not affiliated with or endorsed by the Kev authors, and the credit for Kev belongs to Jared Palmer. The files were compressed by TurinTech with techniques discovered by Artemis. The rest of the Artemis Edge collection is on Hugging Face. For a version tuned on your own decisions or built for your hardware, book a call.